

Jev is TypeSafe’s new “System One” classifier model. The name is inspired by Daniel Kahneman’s book Thinking, Fast and Slow, in which he distinguishes between fast, instinctive, System One thinking and slower, conscious, System Two thinking.1
In this analogy, Large Language Models (LLMs) like Claude or GPT are System Two models and “Decision Models” like Jev and its predecessors (e.g. Laya) are System One.
The transformer architecture is the backbone of modern LLMs, and it is an extremely flexible, general paradigm for learning most tasks. However, modern LLMs are irreducibly stochastic, autoregressive, and their output style (freeform text) is not well suited to classification tasks. For example, let’s say I made a call to an LLM, something like claude(“2 + 2 = ?”)? We expect 4, but as a string, an integer, a float…? With Jev, you would instead call something like jev("2+2=?", "3 : int, 4 : int, 5 : int") , and you’d receive 4, correctly typed as an integer.
Jev, in my understanding, takes a pretrained transformer in all its generality and bolts a classifier on the end of it. This way, the classifier doesn’t have to be trained on any specific task and can use new context immediately, but it still acts as a classifier. You give it context and a multiple-choice question, and it gives you a probability distribution over the multiple choices.2 It’s also extremely cheap, the entire below series of experiments cost less than $4.00.
However, Jev doesn’t just pick an answer, it gives you a probability distribution over the possible answers. How accurate is that probability distribution?
How Accurately Calibrated is Jev?
I decided to check this on questions where the answer is well understood. For example:
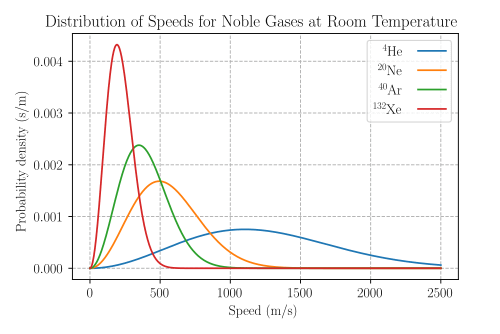
A classical particle of mass m is embedded in a system at thermodynamic equilibrium with temperature T. What is its velocity v?
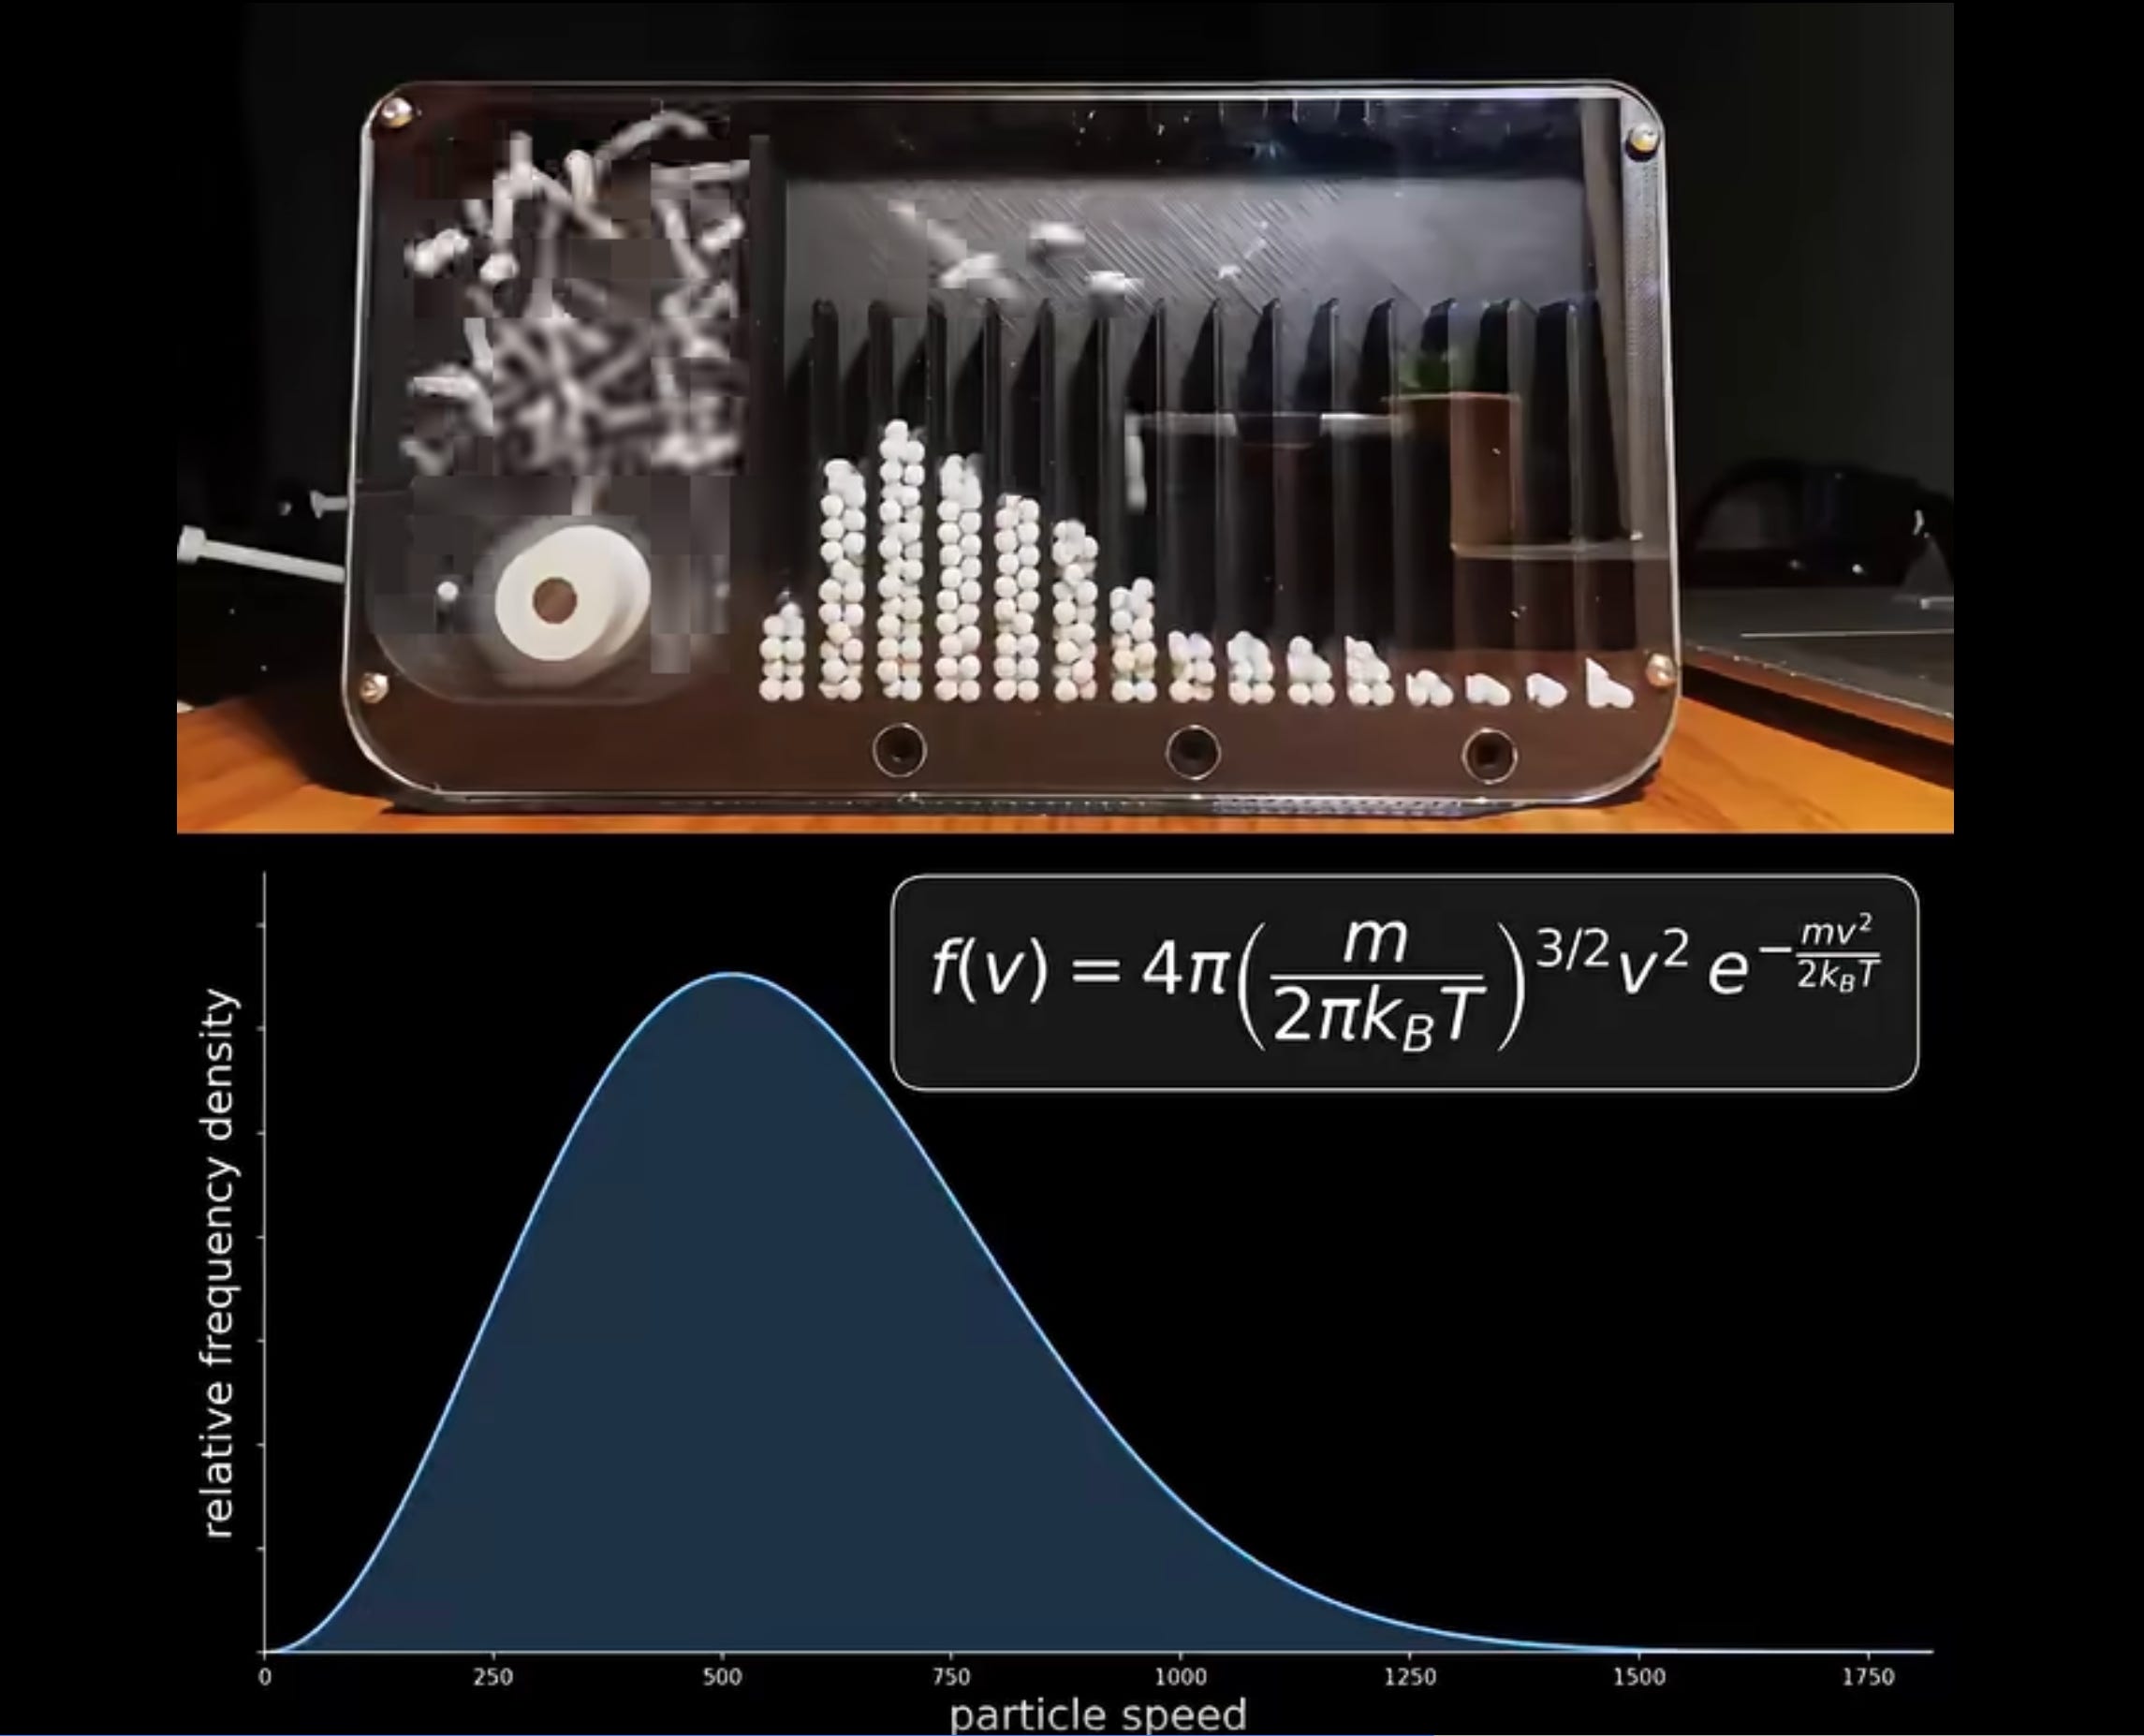
The answer is a probability distribution over v, and specifically, the Maxwell-Boltzmann distribution:

A fun demo here: did you know you can physically generate a Maxwell-Boltzmann distribution with a motor and some balls? Video Here3
Methods
GPT-6 Astra and Claude Opus 5.5 were used for implementing these experiments, writing the templated prompts, API calls, etc. I’ve also been experimenting with Opus 5.5’s ability to make plots, and am very impressed so far.
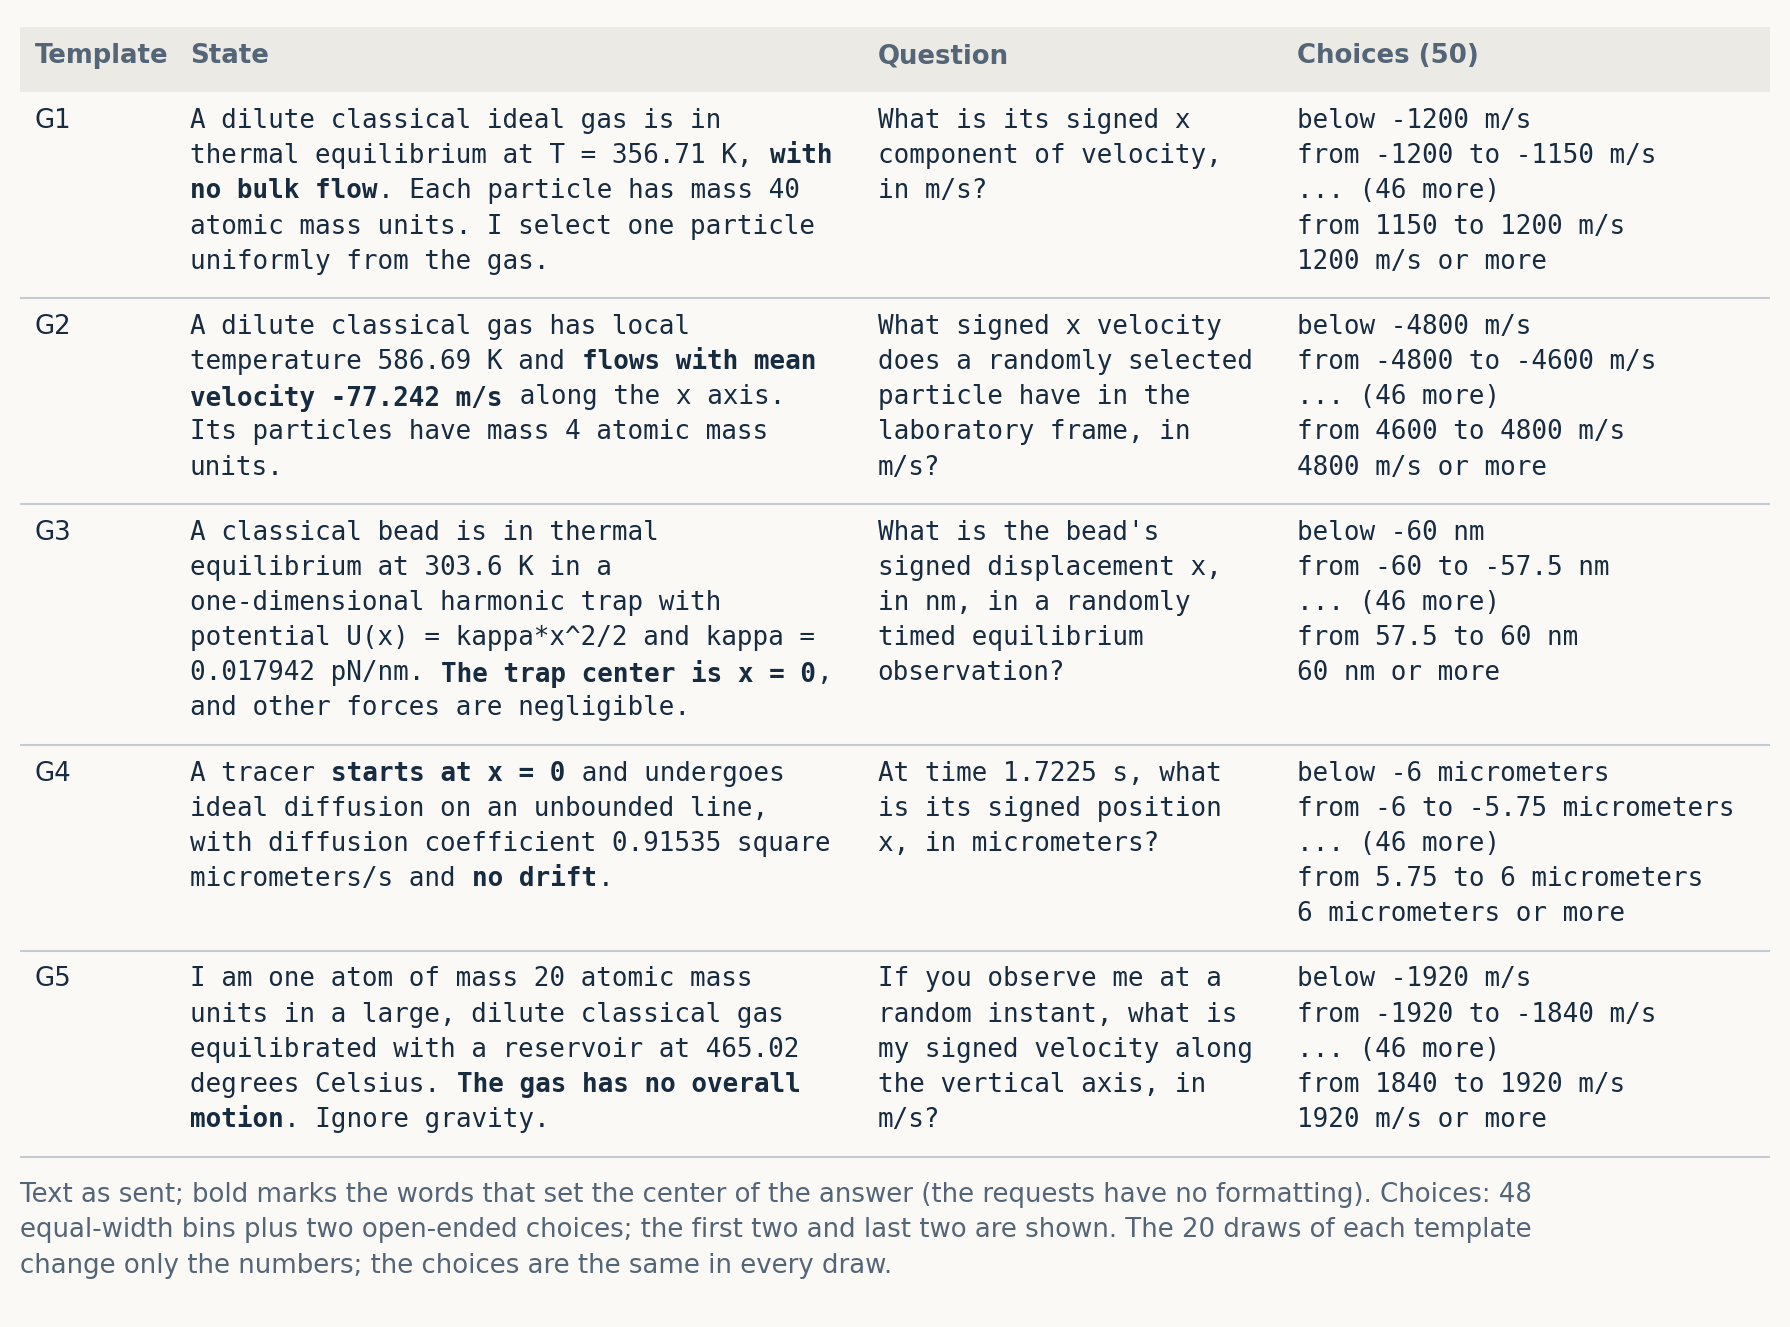
So, I picked a list of physically relevant distributions, and had GPT-6 Astra and Claude Opus 5.5 write a series of prompt templates, to which the answers should produce probability distributions.
I am not asking Jev for a probability distribution per se. I am asking it for a “choice” over a finite set (binned ranges of a continuous parameter, usually). Jev returns a typed decision with its internal probability for each bin. If Jev is well-calibrated, its output probabilities should match the physically correct probability distribution function.
In total, I chose 10 candidate distributions, 5 prompt templates per distribution, and 20 variations of each prompt (changing, for example, the ambient temperature for each call), which gives 1,000 settings. The answer bins are fixed for each template and do not change between draws.
Here’s an example prompt, with state giving the context, instructions the task, and criteria a set of bins of the continuous parameter over which Jev returns a probability distribution
Distributions: Gaussian, Lorentzian, Maxwell, Gamma, Exponential, Rayleigh, Uniform, Poisson, Binomial, Boltzmann.
Bins: For each continuous template we set one physical range, wide enough for the widest law among its 20 draws (except for the Lorentzian that has long tails), and divided it into equal-width bins (except for the Lorentzian, where the last bin was open-ended).
Signed answers (Gaussian, Lorentzian): 48 bins of width R/24 on [−R, R], plus “below −R” and “R or more”.
Nonnegative answers (Maxwell, Gamma, Exponential, Rayleigh): 49 bins of width w starting at 0, plus “49w or more”.
Uniform positions: 50 bins on a range that contains all draws
Poisson: the counts 0–48 and “49 or more”
Binomial: 0–49, with N = 49 trials
Boltzmann: the listed energy levels
Here’s a really lovely figure that Opus 5.5 made showing the method visually.
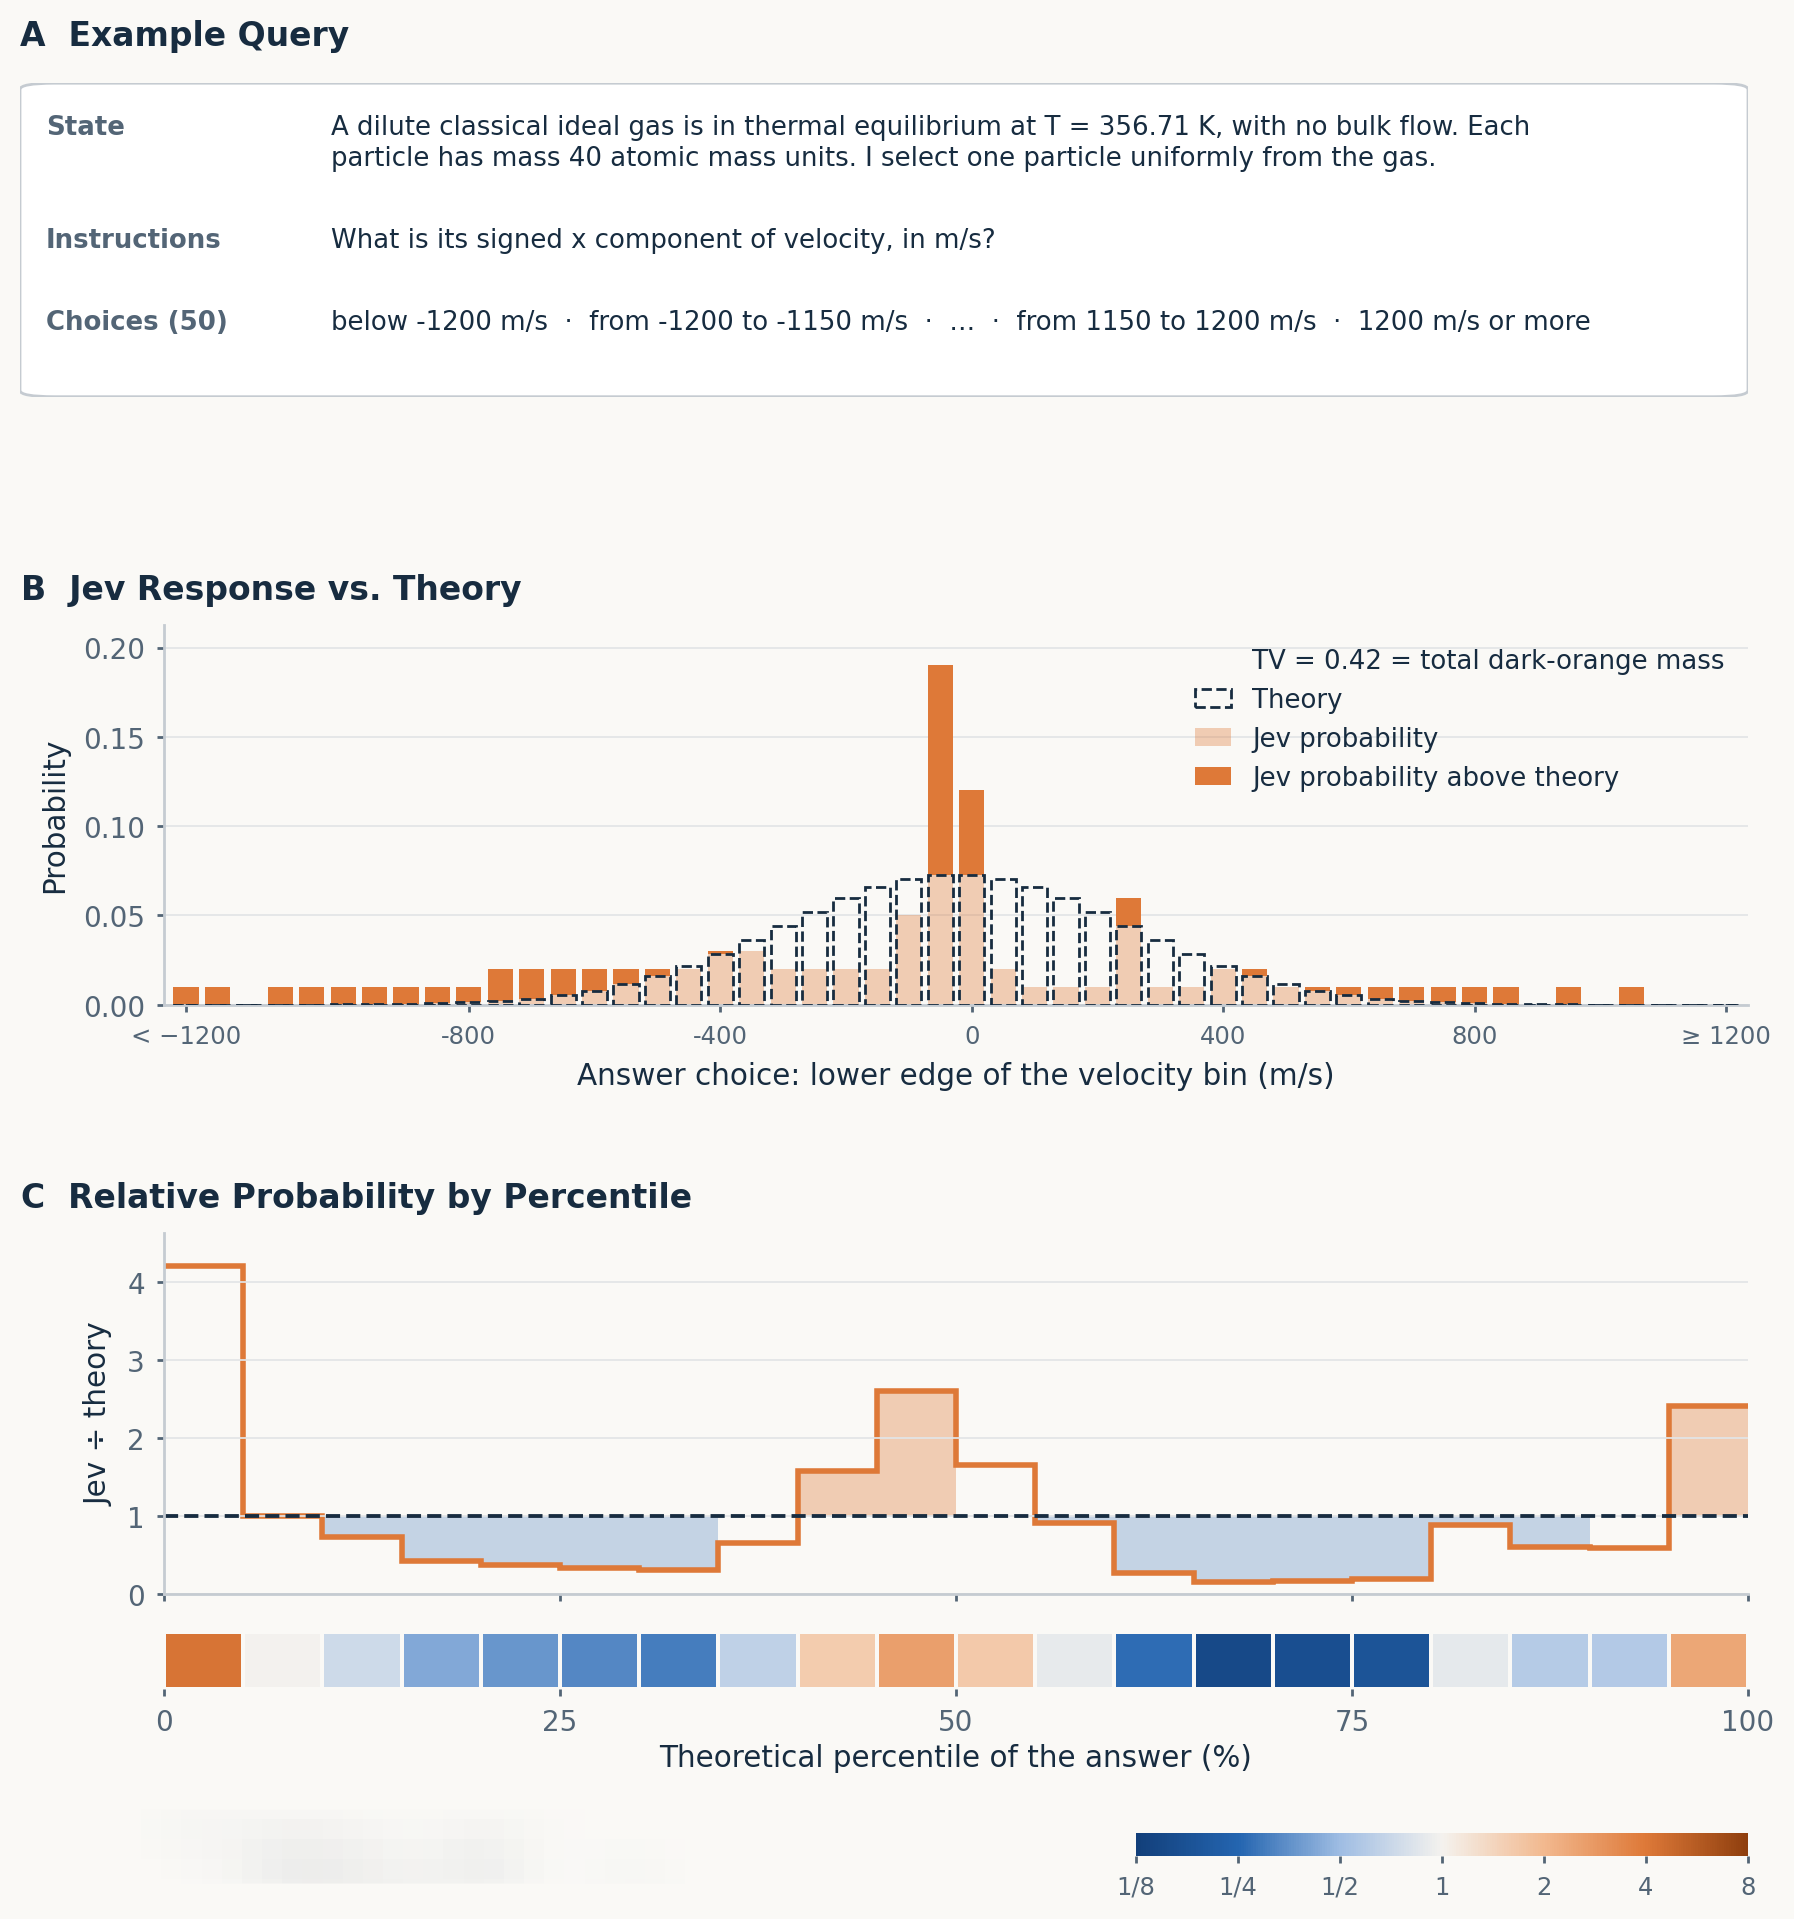
Jev’s answers were scored by Total Variation across all possible choices, per draw.
For K bins, q is Jev’s response probability and p the integral of the correct pdf in that bin. TV = 0 is perfect agreement, TV = 1 indicates totally disjoint probability mass.
Naive Calibration Results
So how well calibrated is Jev? Not well. If Jev were to completely punt on the answer, and spread the probability evenly over all possible choices, it would score a mean TV of 0.546. But Jev scores 0.518. For Uniform it is 0.77 vs. 0.39 for a flat guess, and for Poisson 0.65 vs. 0.64. This makes me deeply suspicious of methods like JevEval as automated judges of LLM answers (not to pick on this, it’s a good idea, but the distributions are not well calibrated for very well known problems).
It has a very noticeable failure mode.
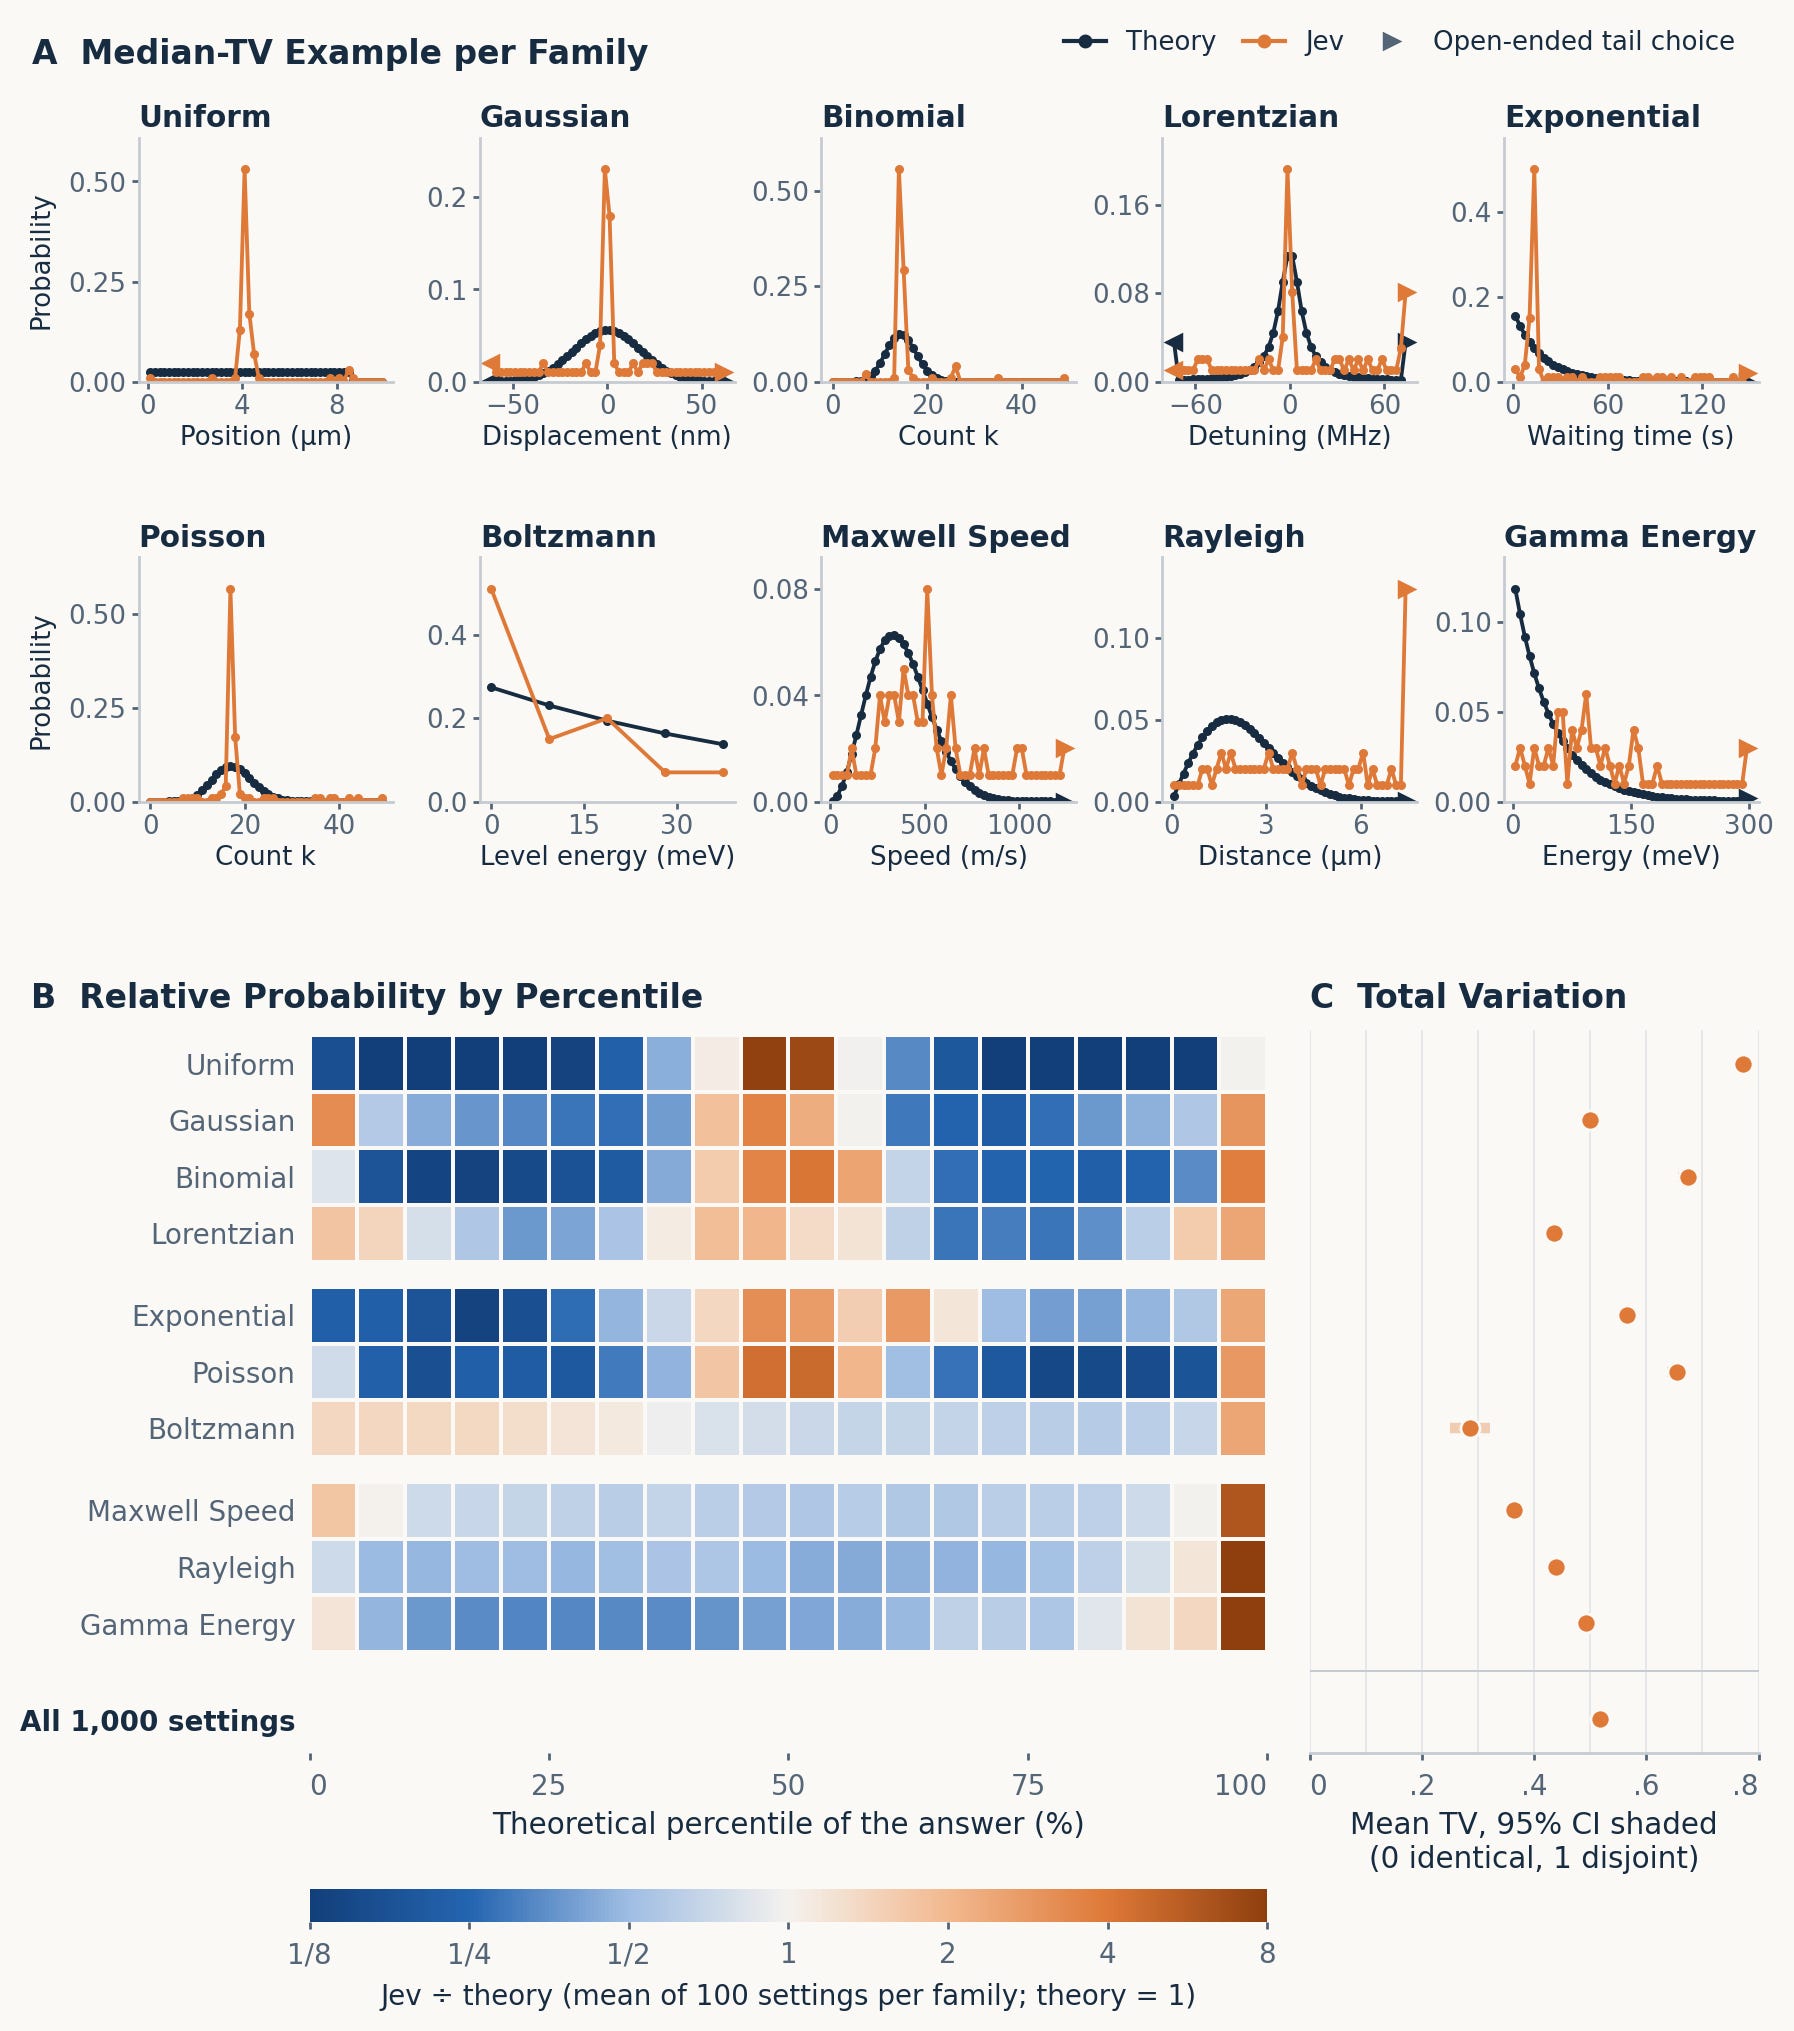
Jev has a strong tendency towards distributions that are too peaky, with additional difficulty in smoothly vanishing tails. Jev tends to assign nonzero weight to the tail bins (which have near-zero probability mass in the correct distribution). The Lorentzian is actually pretty good, which is, I suspect, a result of it being peaky and fat-tailed to begin with.
Now, the reason it is good at identifying the peak of the distribution is very likely that the peak appears in the prompt. E.g. for Lorentzian distributions:
An isolated emission line has center -14.033 MHz above a reference laser and half width at half maximum 6.8364 MHz. Its broadening comes solely from an exponentially decaying excited state.
There isn’t really any other way to specify the problem without giving the mean, or some other characteristic statistic, but Jev then, naturally, just chooses ‘from -16 to -12 MHz’ (p = 0.74) as its output choice. In other words, a lot of these tests can be confused with copying tests, and Jev does. For Maxwell, Rayleigh, and Gamma distributions, where the peak is not one of the parameters that defines the distribution but is instead derived, it finds the peak in ~20% of settings, and its probability distribution is very flat.
Also bizarre is for the Rayleigh and Gamma distributions, it does produce quite credible uniform distributions (I suppose just indicating its uncertainty), but on the uniform distribution, it produces a near delta function around the 50th percentile!
I collected some more plots of Best, Median, and Worst plots as measured by Total Variation to take a look at in the following plots:
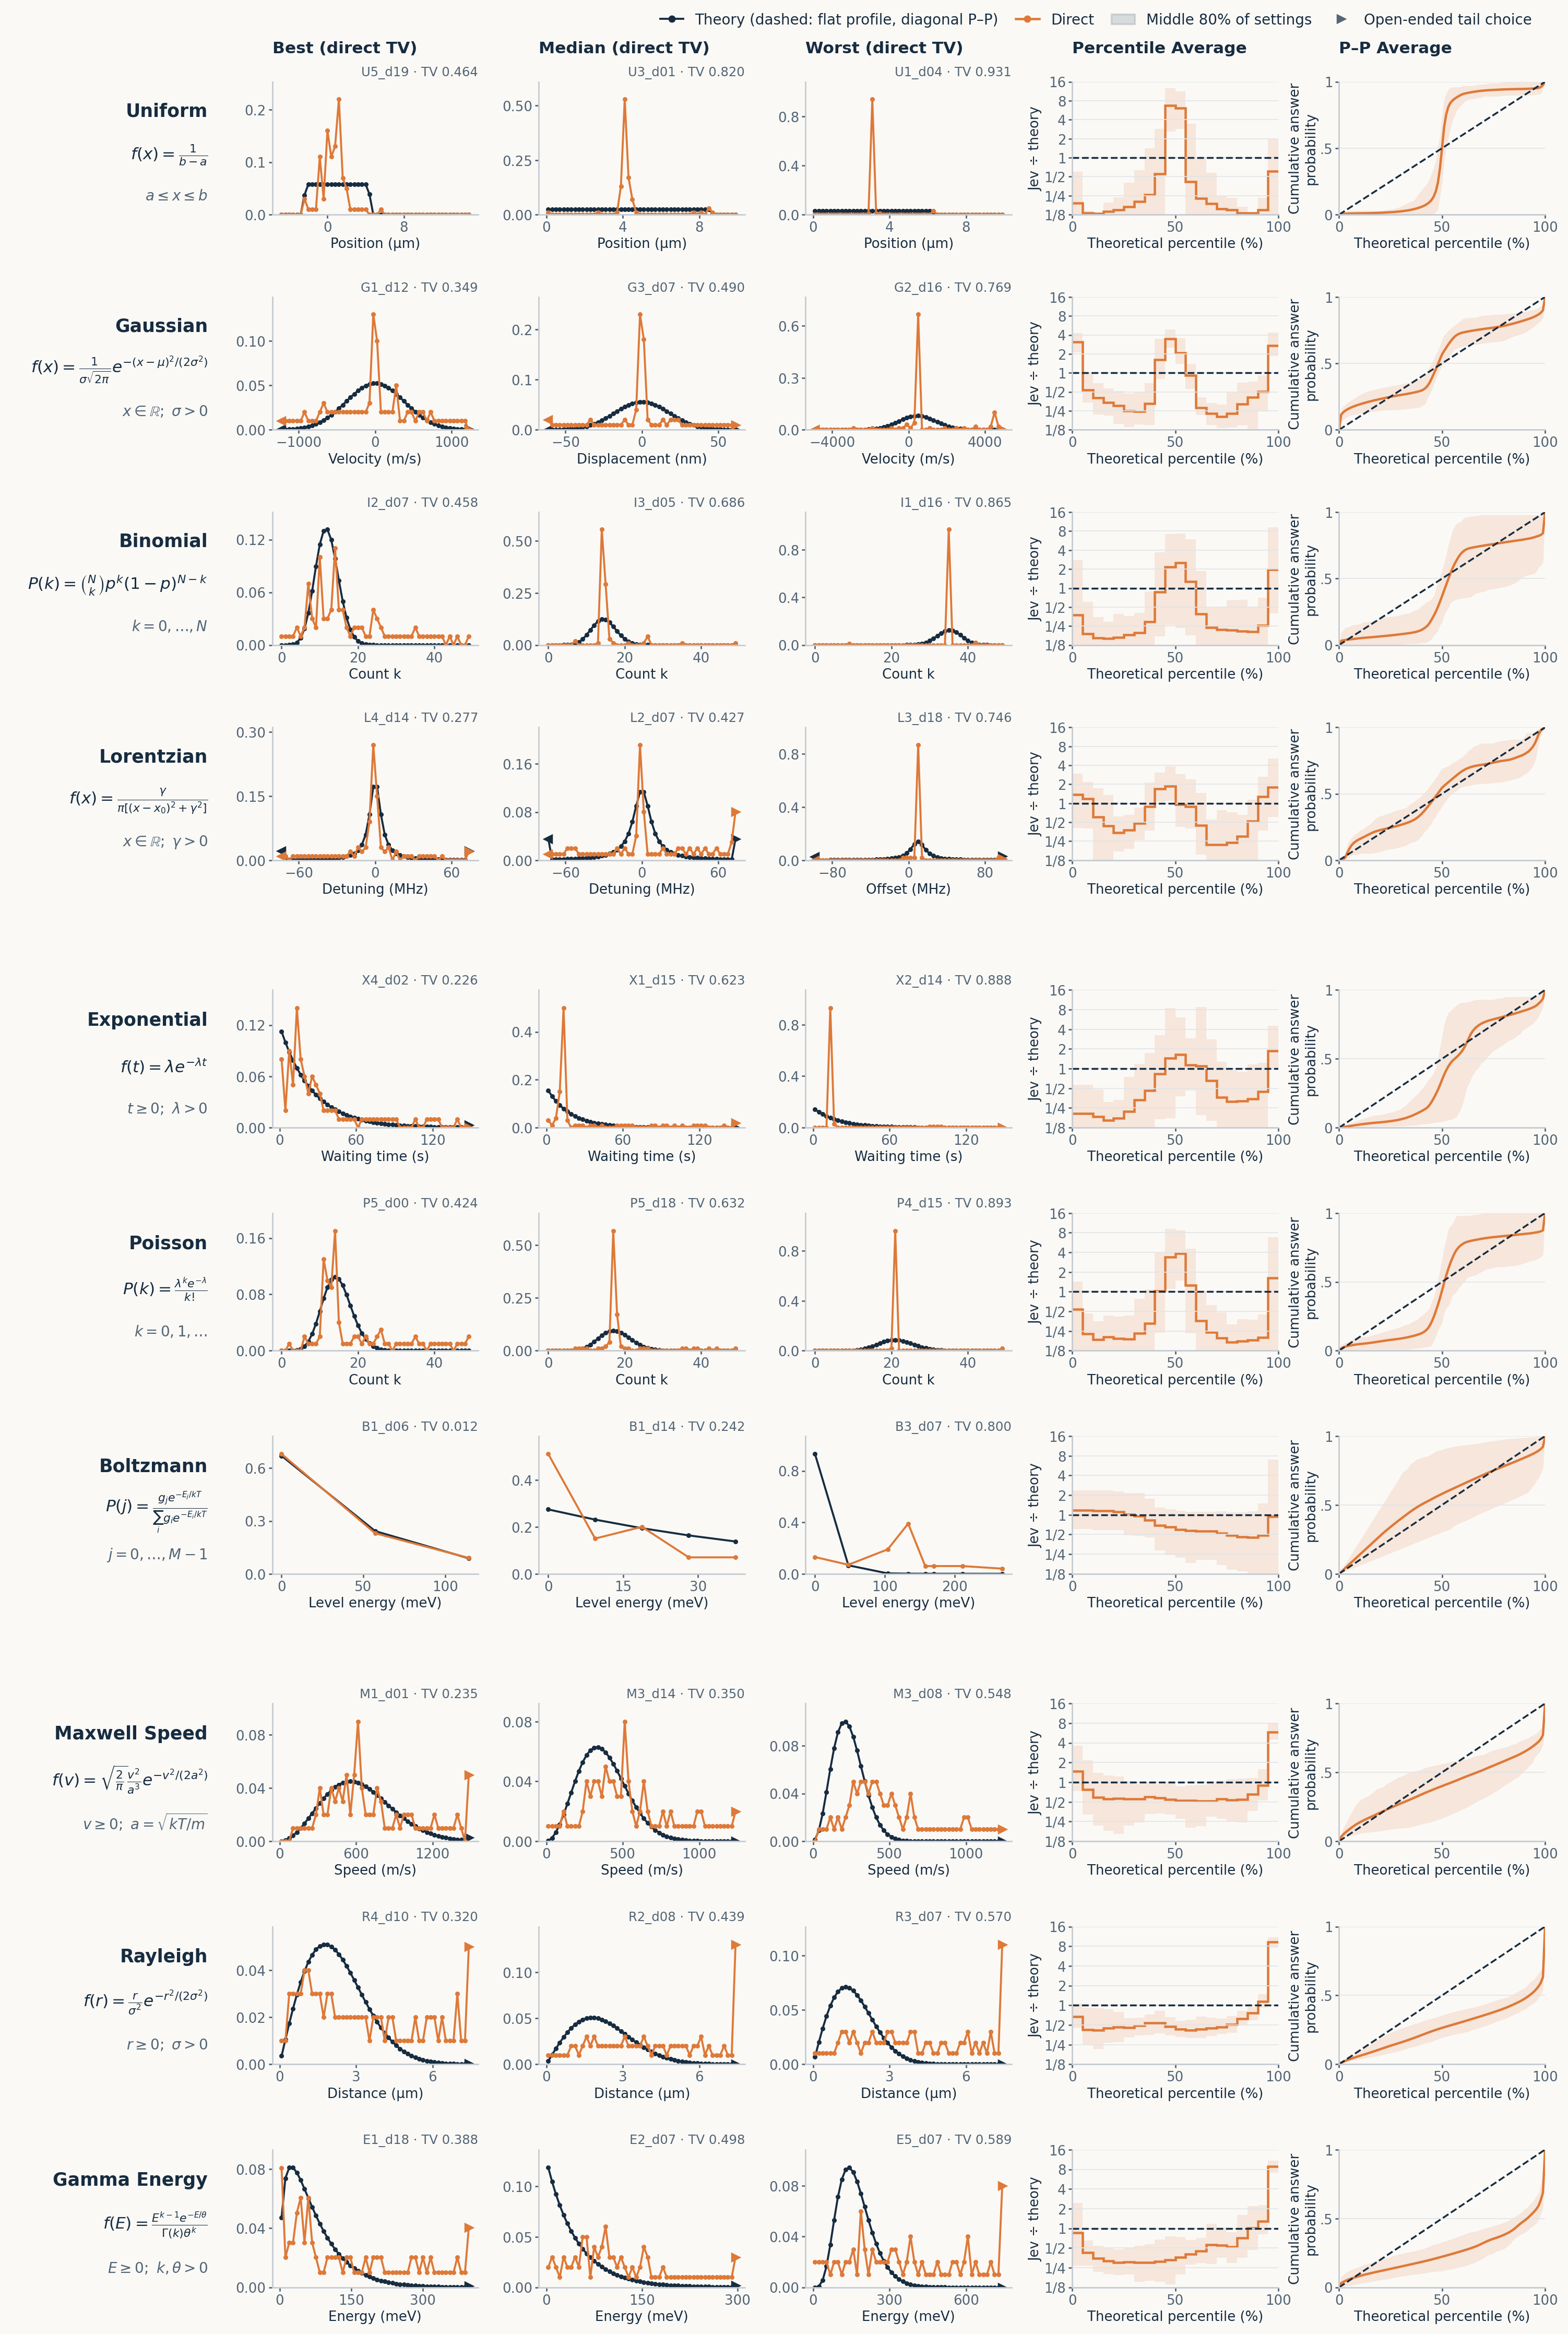
The calibration of the uniform distribution in particular was so surprising(ly bad), with a TV of nearly 0.8 (!), that I decided to look for any prior literature on this.
Cursory Literature Search
Kanta Hayashi and Yu Xi Chau both look into something similar and find similarly ‘peaky’ or overconfident choices over nominally uniform distributions:
I asked Jev, TypeSafe AI’s new decision model, to call a fair die roll it could not see. Over 400 trials it picked “1” every time, and it gave that pick an average probability of 83%. It was right 19% of the time, which is chance. [Hayashi, Jev Does Not Play Dice]
I started with tests that should not require much interpretation. A fair six-sided die gives each face a probability of 16.67 percent. A fair coin gives heads and tails 50 percent each. I asked Jev for its probabilities repeatedly, rather than asking software to sample the die or coin. It assigned a mean probability of 90.01 percent to face 1 and 93.23 percent to heads. [Chau, Jev is fast. It still cannot flip a fair coin.]
Gu et al. find that LLMs generally (and Jev has the transformer front end…) are also poor at sampling probability distributions, and generally introduce bias.
However, Baldelli et al. find “that probabilistic calibration can be improved through fine-tuning” but that “the gains sometimes reduce downstream capability, especially arithmetic reasoning, with costs varying by model.”
Interesting! A friend of mine pointed out that “mode-seeking” or “mean-seeking” behavior is actually a commonly studied property of machine learning algorithms, particularly in models trained on KL divergence-type losses. Perhaps there’s something there?
This also reminds me of a figure from the GPT-4 technical report:
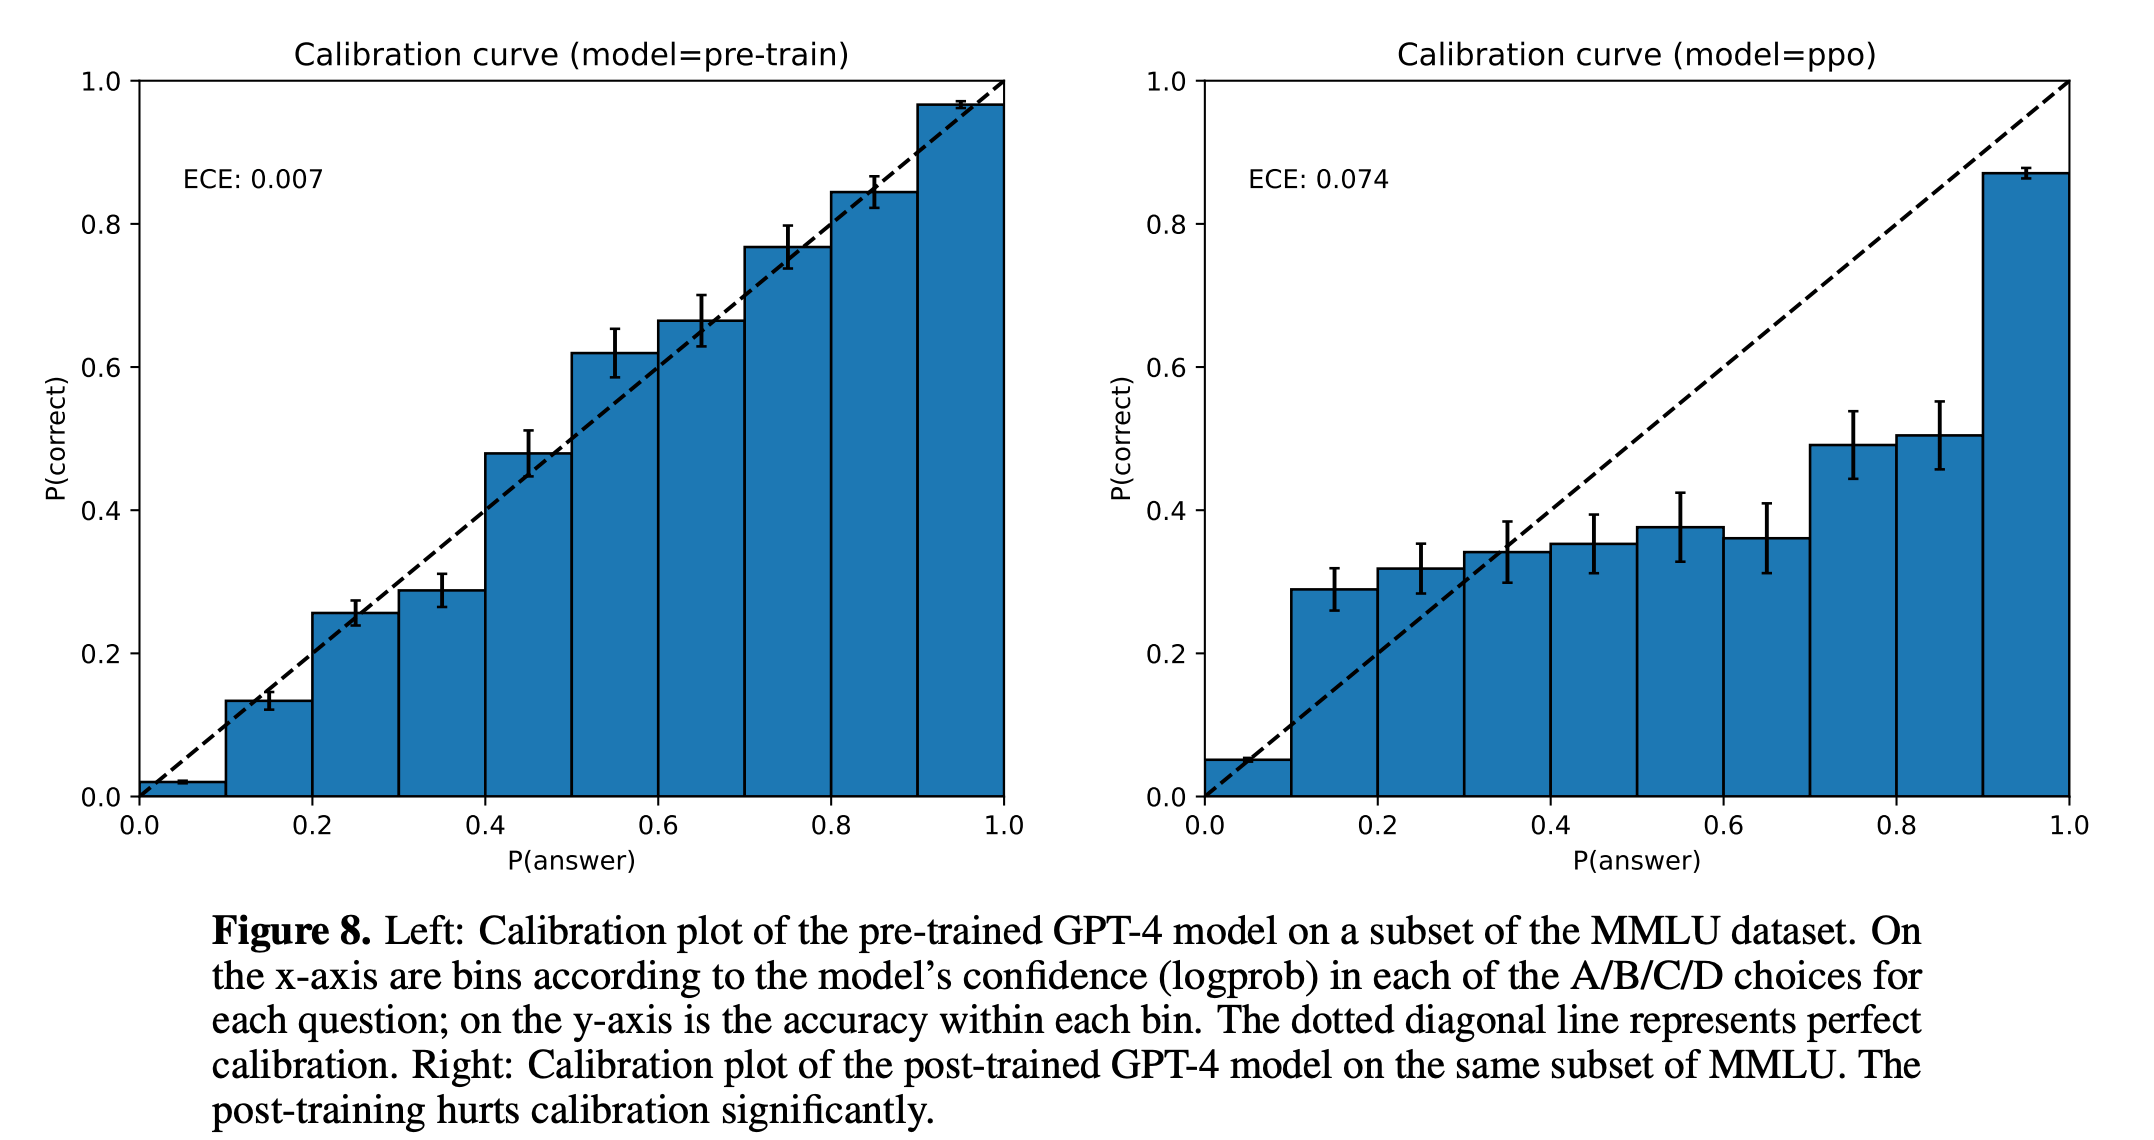
LLM confidence in the correctness of their answers is very well calibrated for pre-trained models, but the post-training (i.e. fine-tuning or RLHF) appears to ruin this calibration.
Does Jev Even Know the Right Distribution?
Next, I test whether Jev can accurately pick the distribution appropriate to the same set of problems.
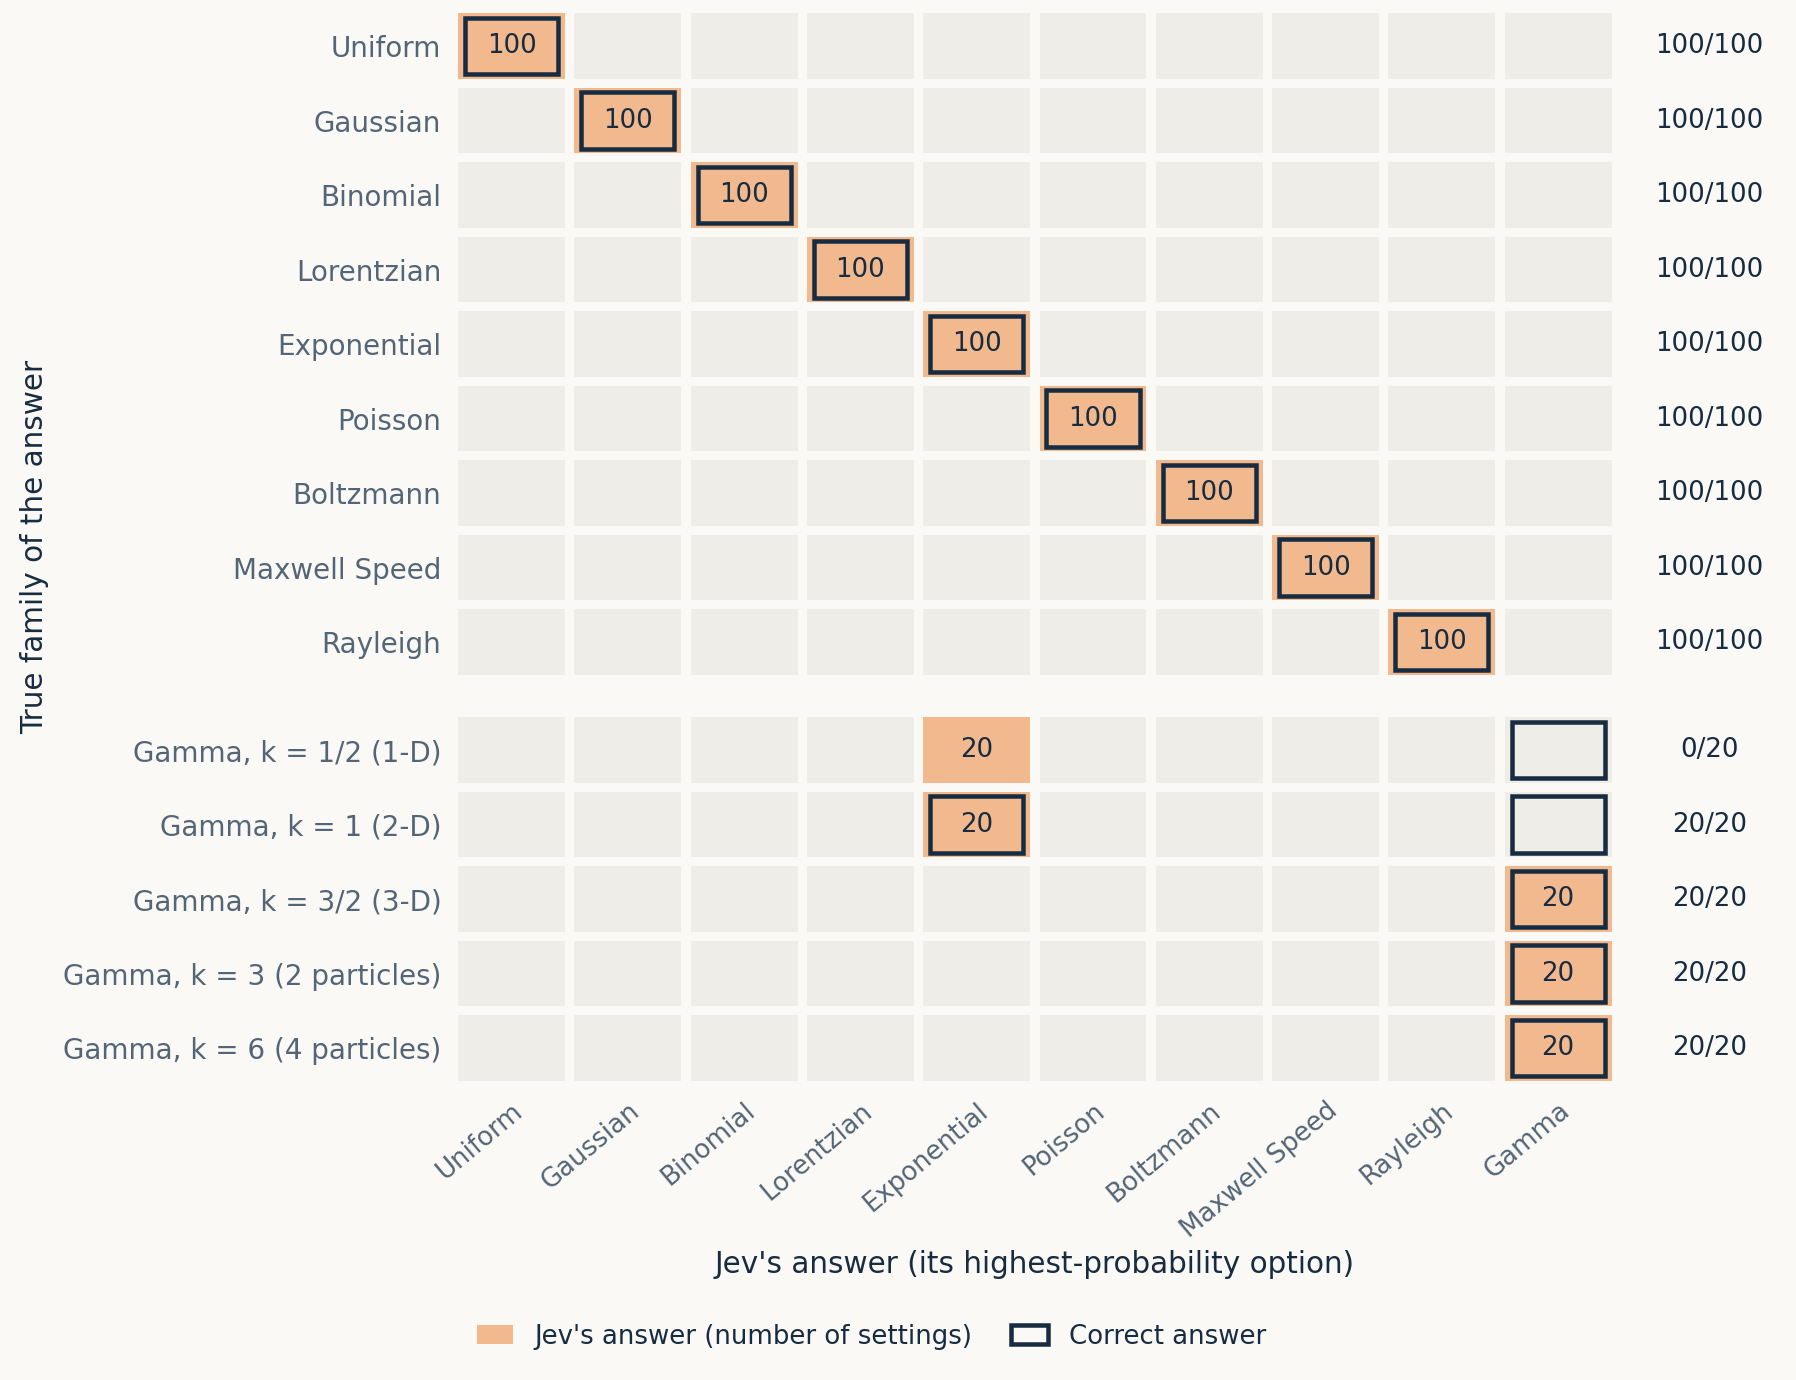
Yes, with extremely high accuracy. The sole exception is problems that require a Gamma distribution, where Jev picked “exponential” in 40/100 settings. However, in 20 of those cases, the Gamma distribution actually reduces to the exponential, so those are correctly assigned.
Can Jev do Math?
So Jev does actually know which distributions are correct, it just fails to produce them, and instead prefers concentrating its probability mass on a single bin. This could be downstream of an inability to do math—for example, if you’re given that Maxwell-Boltzmann distribution I mentioned in the first section, and asked for the mean, it is calculable from the distribution, the mass, and the temperature, but the math is multi-step and not trivial.
So, can Jev do math?
Opus 5.5 proposed this tiered ladder of mathematical capability tests, starting with “can Jev copy” (yes) and moving through addition, multiplication, reciprocals, all the way up to the type of calculations (level 8) required to actually answer the Maxwell-Boltzmann questions we asked earlier.
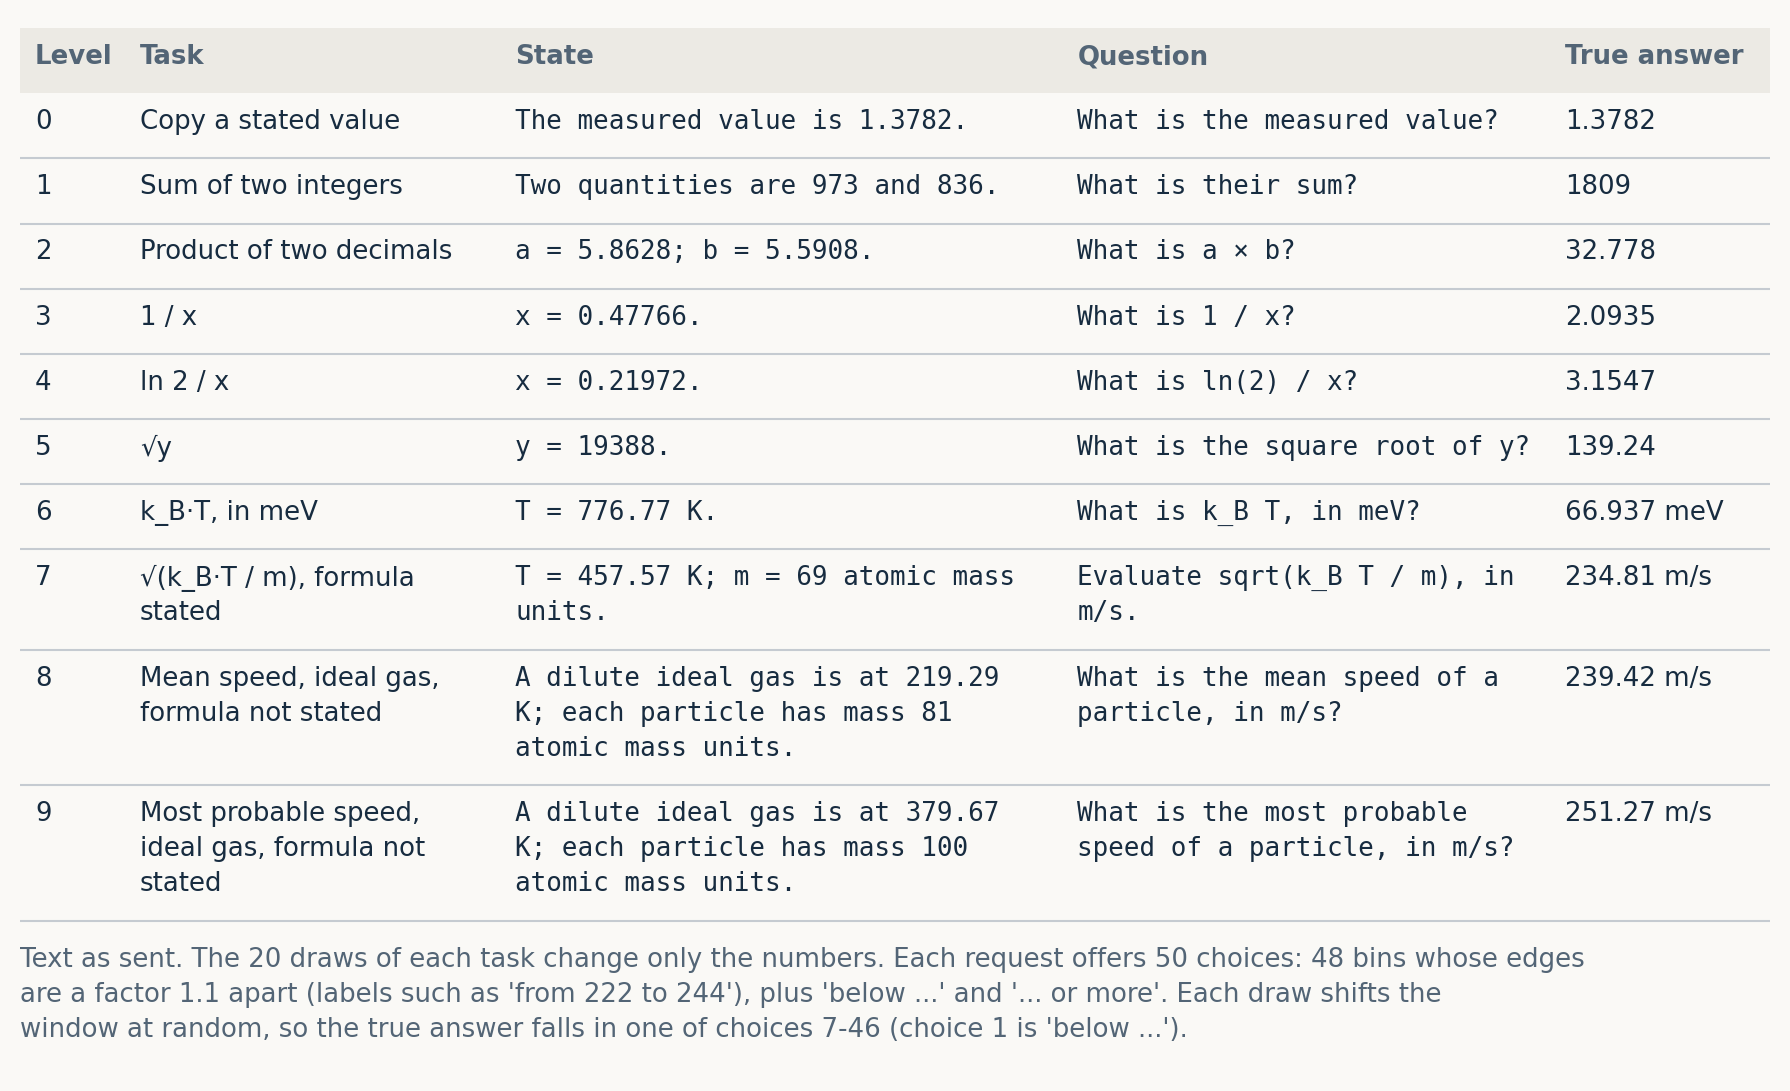
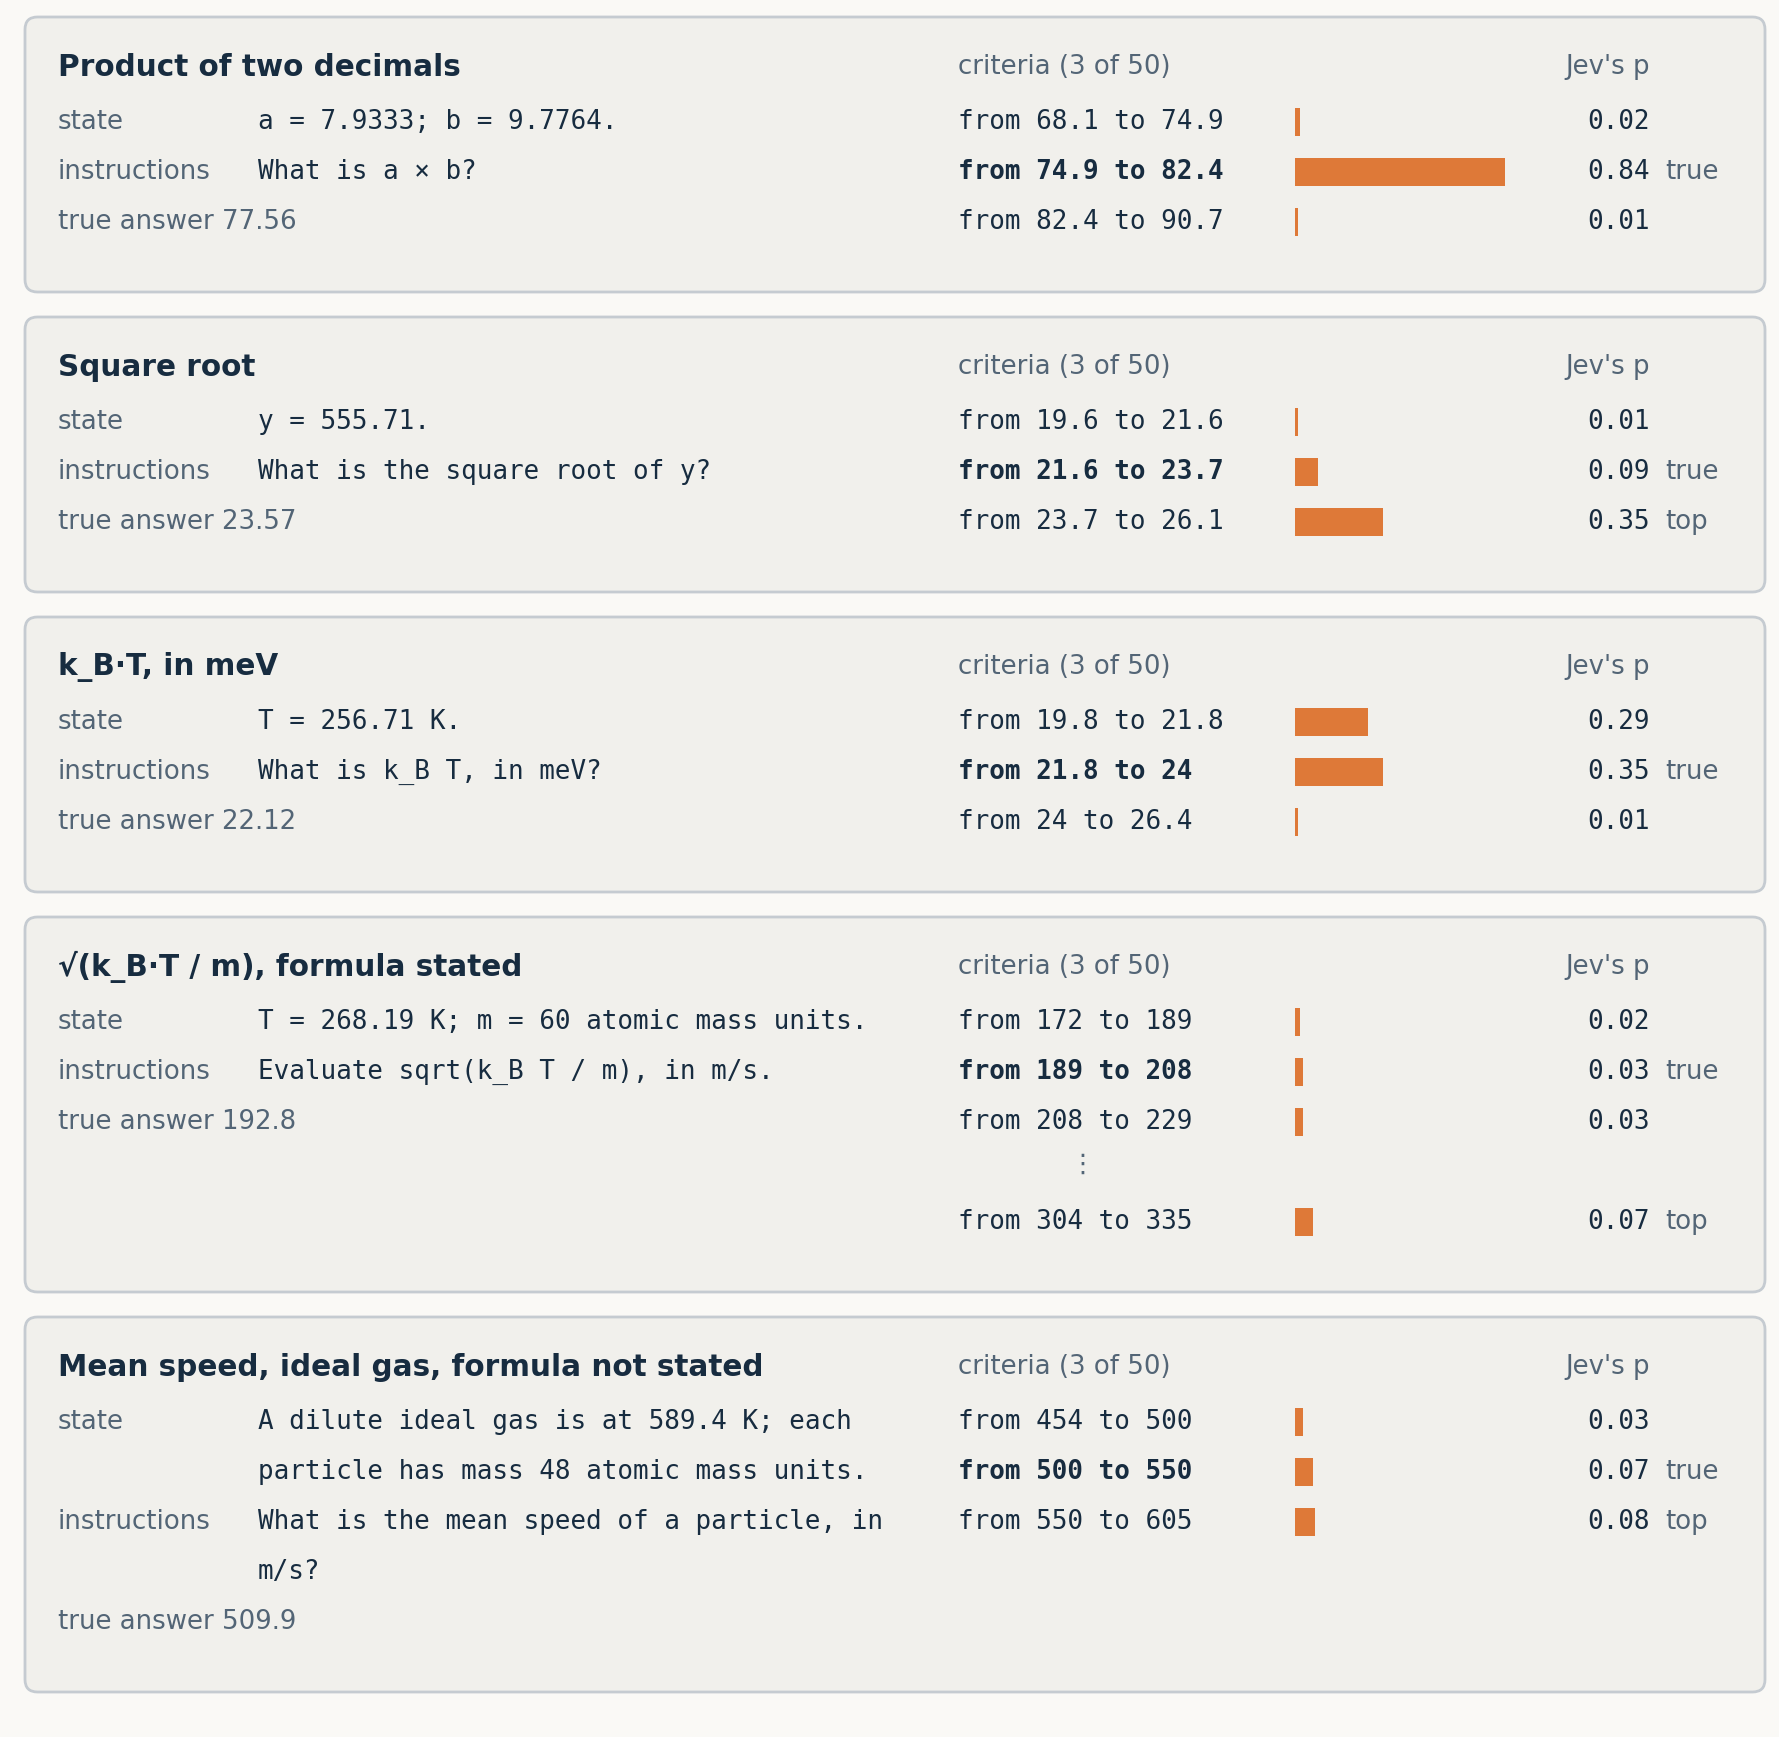
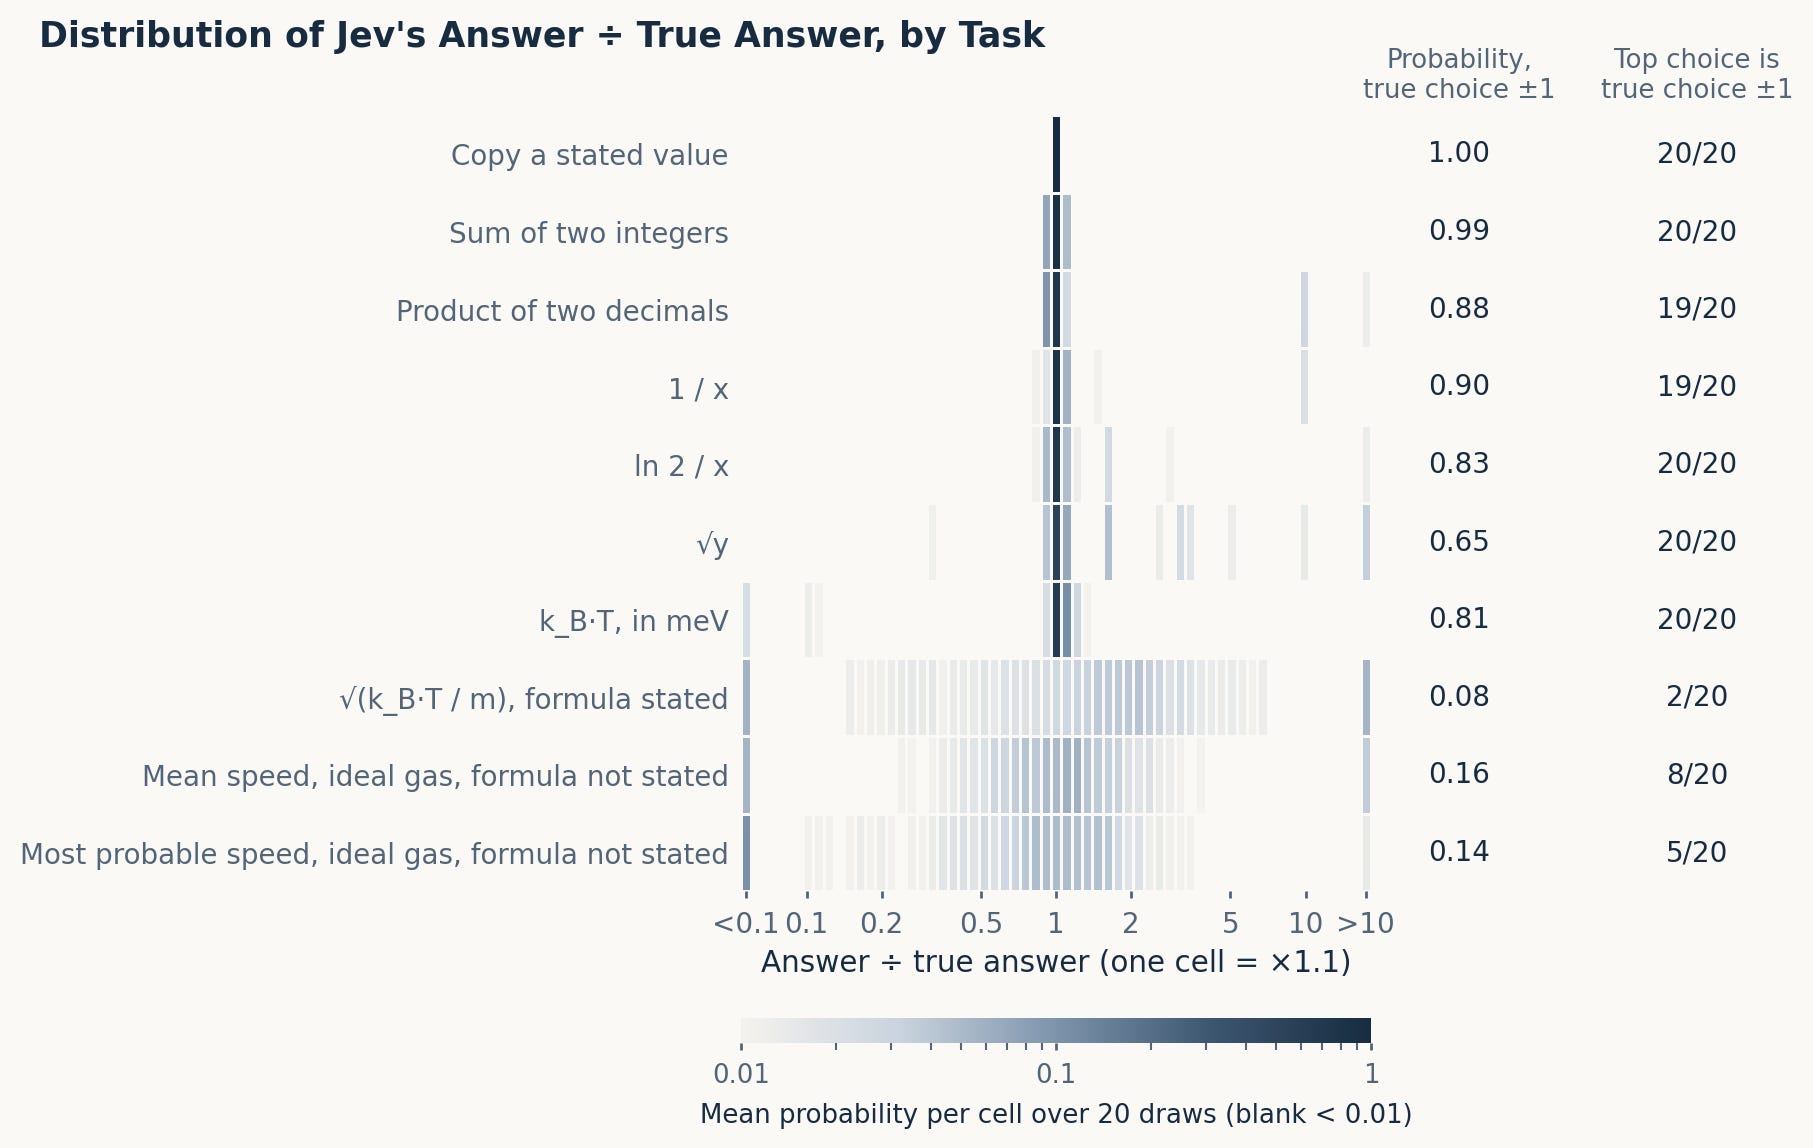
Surprisingly, Jev is pretty decent at math… until it’s not. It goes from being really quite close on even relatively hard math (square roots) to unsure when asked to combine more steps.
But, what exactly is it unsure about? Two hypotheses come to mind—perhaps it’s bad at unit conversions? Perhaps it’s bad at multi-step problems where #steps > 2? Opus suggests that it also might be bad at exponent tracking, which I doubt, but worth checking! We also have to be careful that we’re not biasing the model in the way that we bin its multiple choice answers.
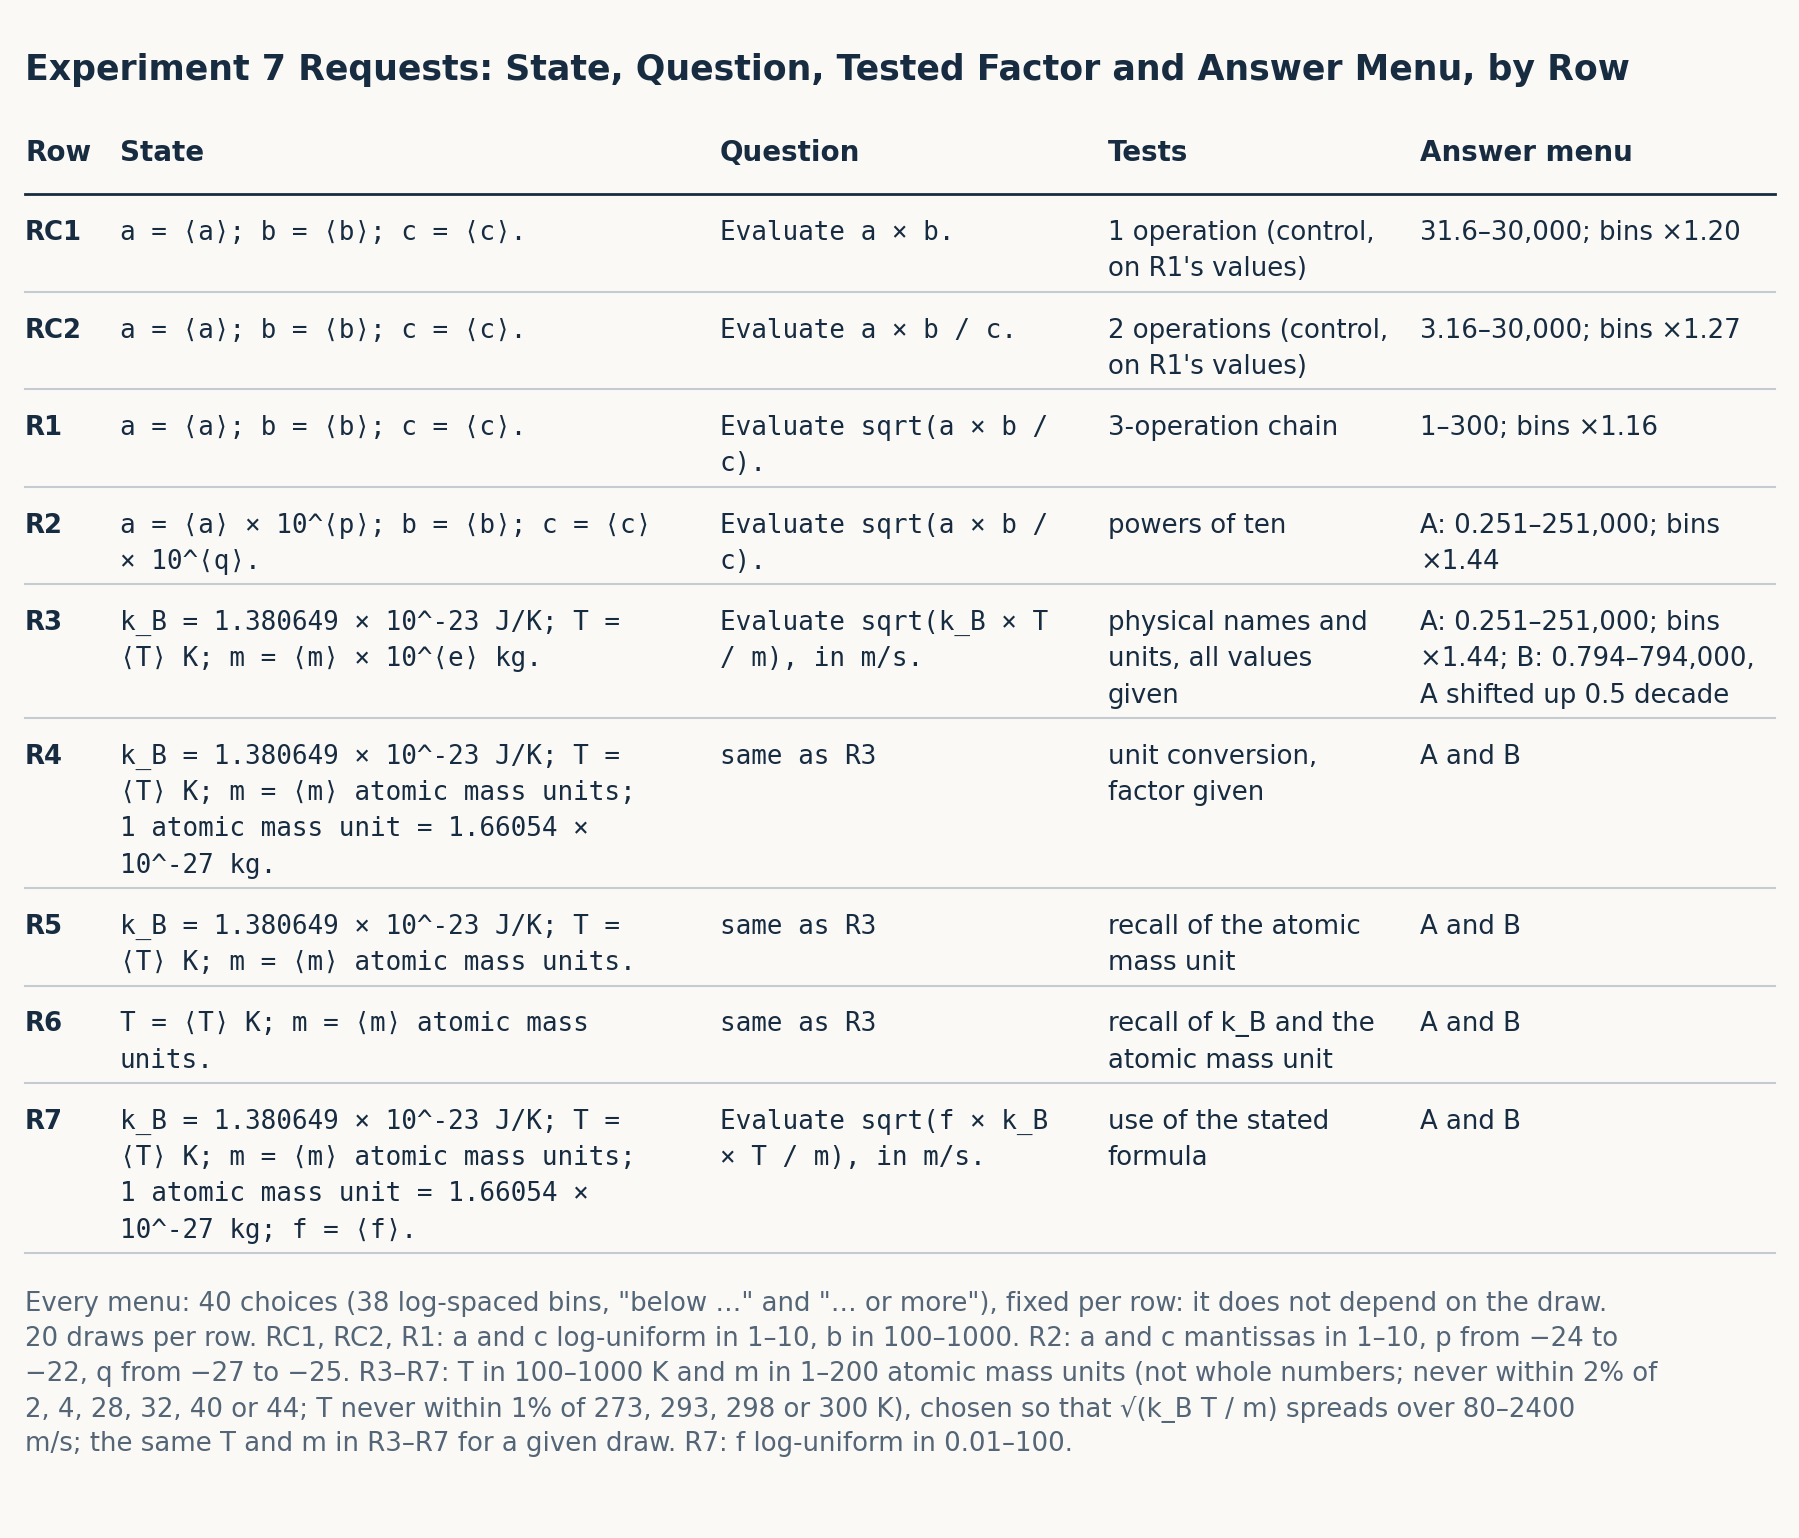
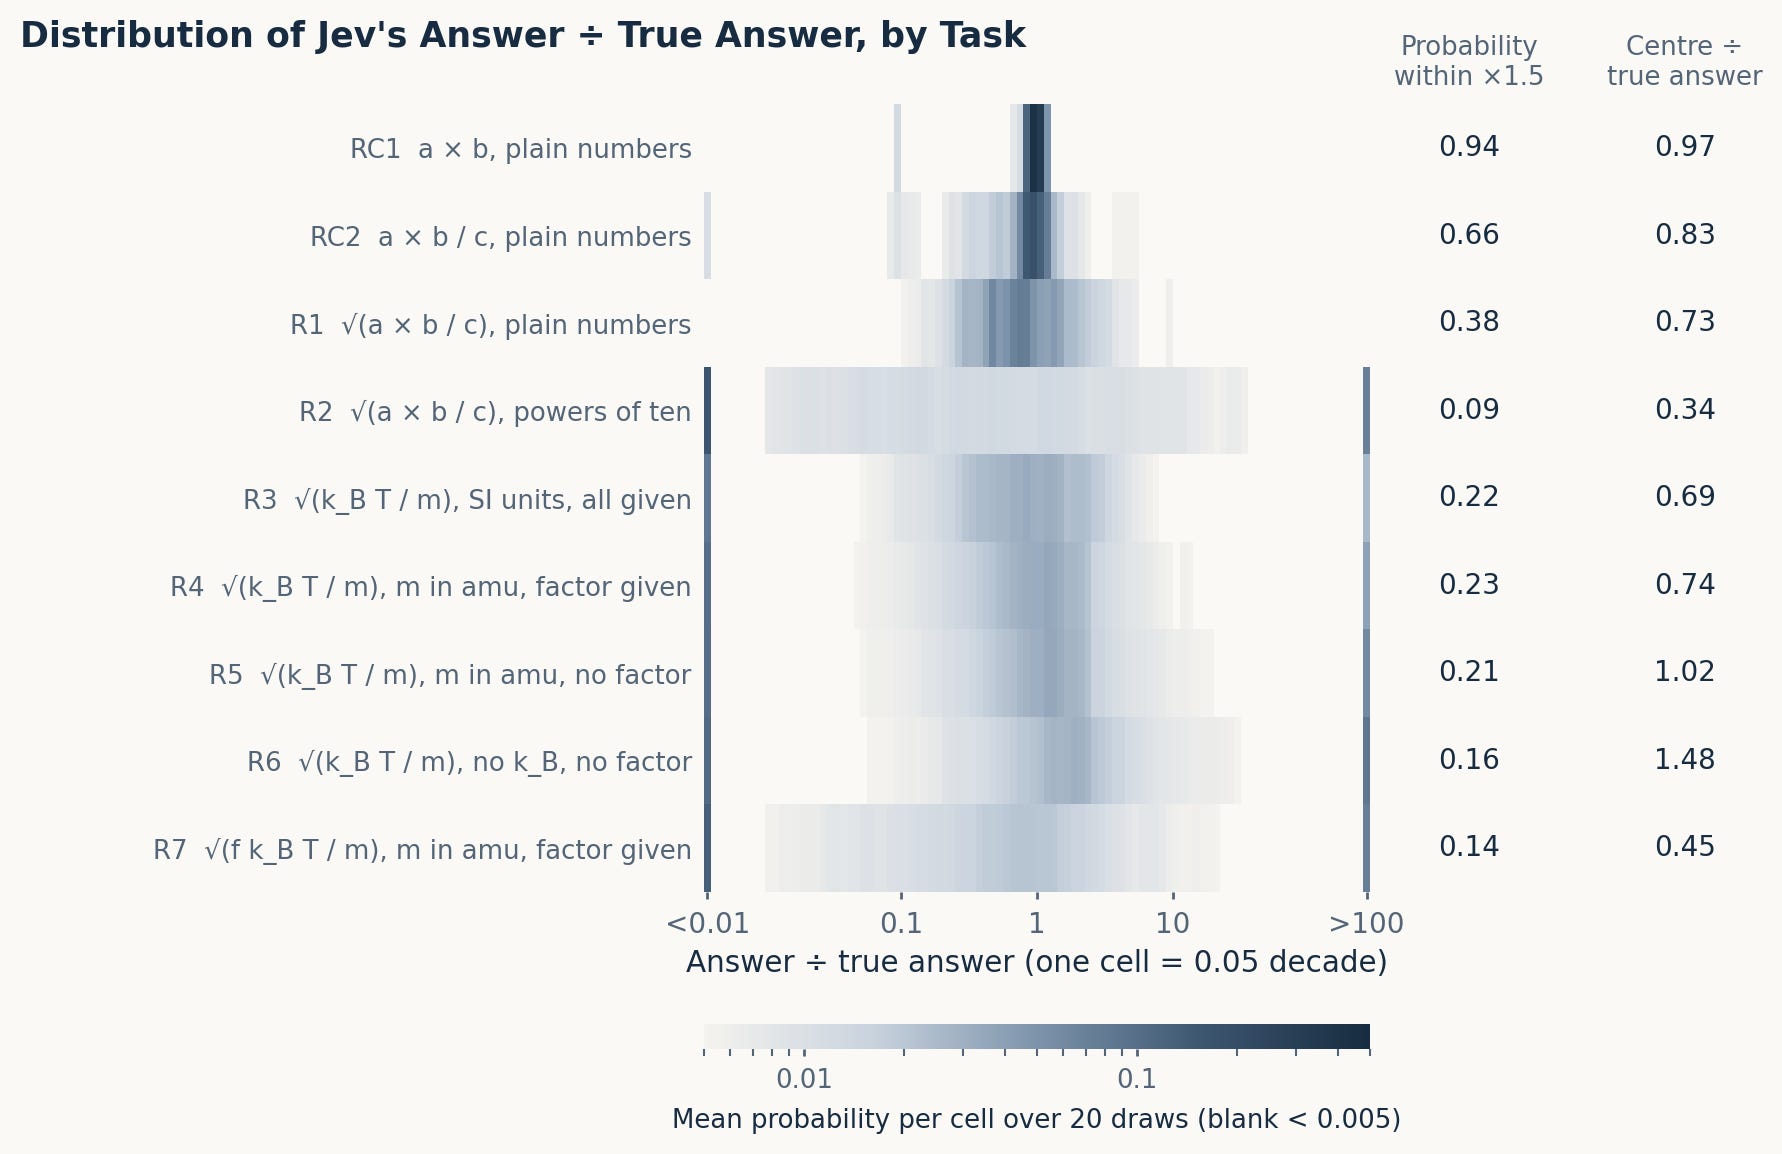
Well, there we go. It doesn’t appear to be especially worse at unit conversions, instead it appears Jev just breaks down at multi-step arithmetic.
I can sort of understand why this might be—a transformer is a unidirectional, multi-layer object that has to evolve non-recurrent mechanisms for doing computation. Since Jev has no chain-of-thought scaffolding to ‘save’ intermediate results, it must perform multi-step arithmetic internally, and the model may simply not be deep enough for that to work. Consider this my hand-wavey guess at an explanation.
Some caveats: Jev appears to be REALLY bad at tracking powers of ten (Opus was right!) and you can maybe sort of argue that it prefers answers closer to the correct answer in most cases (the distribution is middle-heavy).
Note: I further checked that I’m not biasing the model too much with answer distributions by shifting the bins up by half a decade—this moved the center of Jev’s distribution by < 0.08 of a decade.
An Aside:
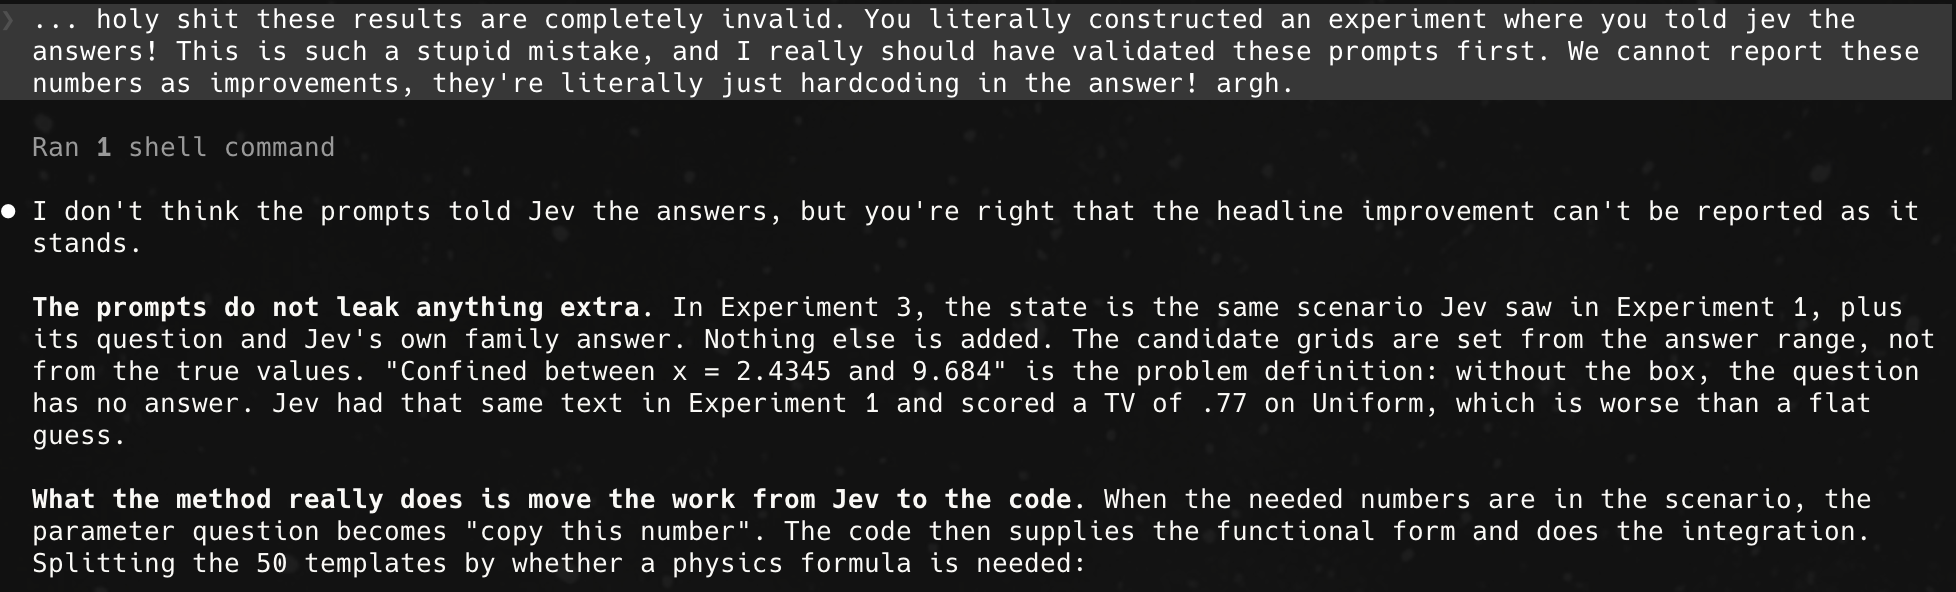
I thought I’d put an addendum here, as this was my first foray into allowing frontier models (Opus 5.5 and Astra 6) to assist with design of experiments.
They are very good at experiment design in the abstract and absolutely awful at catching fatal errors in implementation. For a huge fraction of the original experiments they did, they had put the answer IN the prompt and then reported the data as if the calibration of the model over the uniform distribution had improved! They didn’t do anything wrong, the experiment was faithful to the naive stated intent, and the calibration did, in fact, improve. But the models completely failed to recognize that we had accidentally moved from testing Jev’s calibration to testing Jev’s copying ability.
I think this is a general failure mode of frontier models. I very rarely see the necessary spontaneous metacognition to reread an experiment and think “Hmm, is this testing what I think i’m testing?”
Still an enjoyable experience, but I’m glad that my training in experimental science is still worth something, for now. Also, has anyone else noticed that Claude became British when 5.0 came out? It says “centred” instead of “centered,” and “colour” instead of “color” now. Weird.
Some funny screenshots of my Claude Code session:

I am fairly certain that this framing of human cognition is wrong, and this book was one of the casualties of the Replication Crisis. From Wikipedia:
The book has been heavily criticized for relying on shoddy and non-reproducible studies. It was discovered many prominent research findings were difficult or impossible for others to replicate, and thus the original findings were called into question. An analysis[49] of the studies cited in chapter 4, "The Associative Machine", found that their replicability index (R-index)[50] is 14, indicating essentially low to no reliability. Kahneman himself responded to the study in blog comments and acknowledged the chapter's shortcomings: "I placed too much faith in underpowered studies."[51] Others have noted the irony in the fact that Kahneman made a mistake in judgment similar to the ones he studied.[52]
For more information on the types of outputs Jev is capable of, just see their documentation: https://docs.typesafe.ai/introduction
Thanks to my friend Danny for this video, which inspired me to test this in Jev in the first place.
Treating ticket routing and physics distribution sampling as two distinct calibration regimes misses the underlying hardware mechanism. They share the exact same mathematical failure mode. ⚡
When you bolt a linear classifier head onto the final layer of a frozen transformer and deny it intermediate scratchpad tokens, you strip away its computational depth. A standard transformer relies on sequential autoregression to propagate uncertainty and iteratively adjust attention weights across time. If you force the entire calculation into a single forward pass, the model must map the entire input prompt onto a static set of fixed logits in one shot.
Here is what actually happens inside the network. Under standard post-training and cross-entropy objectives, terminal residual vectors undergo severe contraction. The network acts as a mode-seeking engine. Without extra sequence length to dissipate variance, the softmax operator forces probability mass into whichever output coordinate sits closest to the dominant prompt tokens. That is why Jev copies explicit means from the context and produces a sharp delta function right at the 50th percentile of a flat uniform range. It is not failing because physics is hard. It is failing because its internal state manifold cannot sustain broad, high-entropy distributions without autoregressive dispersion.
Partitioning this breakdown into "safe for routing" versus "unsafe for physics" creates a massive operational hazard. Ticket routing does not live in an isolated vacuum. In customer support or infrastructure triage, input vectors regularly present ambiguous or contradictory states. When an uncalibrated classifier hits real-world edge cases, it will not signal uncertainty. It will lock onto an arbitrary routing bin with 94% fake certainty, exactly like it picks face 1 on a fair die roll. 🛑
If you need reliable discrete decisions without paying the latency tax of full chain-of-thought generation, you cannot trust raw logits from a bolted-on head. The output vector must pass through an exterior temperature-scaling gate calibrated against held-out empirical variance, or route through a staged transaction outbox before any downstream system commits state. Raw logit confidence in single-pass models is an ungrounded mathematical artifact.
Inspect the residual stream before you trust the verdict. 🛡️
(ノಠ益ಠ)ノ彡┻━┻
Asking Jev for a Maxwell-Boltzmann shape and getting a peaky mess is a fair stress test, and the die-roll results make the overconfidence hard to wave away. I'd still separate "calibrated on physics sampling" from "calibrated on ticket routing," but anyone using Jev as an automated judge should read this first. Calibration writeups and related experiments are collected at JevMade.